tweetindex
ES

Alexi Gladstone

@AlexiGlad

ASI whisperer. Working on EBTs/EBMs, XMs, Generative Modeling, World Models, Reasoning. PhD @ UIUC. Prev @flappyairplanes @Meta, @PalantirTech

8 321Followers
808Following
623Posts total
1.3MViews on collected posts

Últimas publicaciones

@AlexiGlad We did this in DeltaWorld, called it BoM. Cool to see that it can improve a DiT! My hesitation is that BoM alone can’t scale to many modes, and doesn’t guarantee noise space coverage. Your Reverse XM is interesting, but wouldn’t it incentivize memorization over general 7.1K views · 34 likes · 0 reposts · 5 replies Open on X →
P.S. Every single one of these results was predicted in advance by Mode Forcing, a unifying and predictive theory of generative modeling. That paper drops soon! If you work on image gen, video gen, world models, robot policies, or MDLMs, exploration should be a drop-in 13.6K views · 165 likes · 8 reposts · 7 replies Open on X →
[10/N] Website: https://t.co/rKTx0sZq2j Paper: https://t.co/hGV6QaWdeC GitHub: https://t.co/gob266aL4j Hugging Face: https://t.co/qvjctxpKRG Huge thanks to @du_yilun, @hengjinlp, @LaudeInstitute, Flapping Airplanes, @bradenjhancock, @k_tighe @HessianFree and so many others for h
1:02
15.8K views · 132 likes · 12 reposts · 3 replies Open on X →
[8/N] Does exploration also help generalization? During generative pretraining, the same input often gets different valid targets. To a model that can only predict one thing, this looks like noise, and fitting noise is memorization. With exploration, each prediction commits to
14.7K views · 67 likes · 5 reposts · 3 replies Open on X →
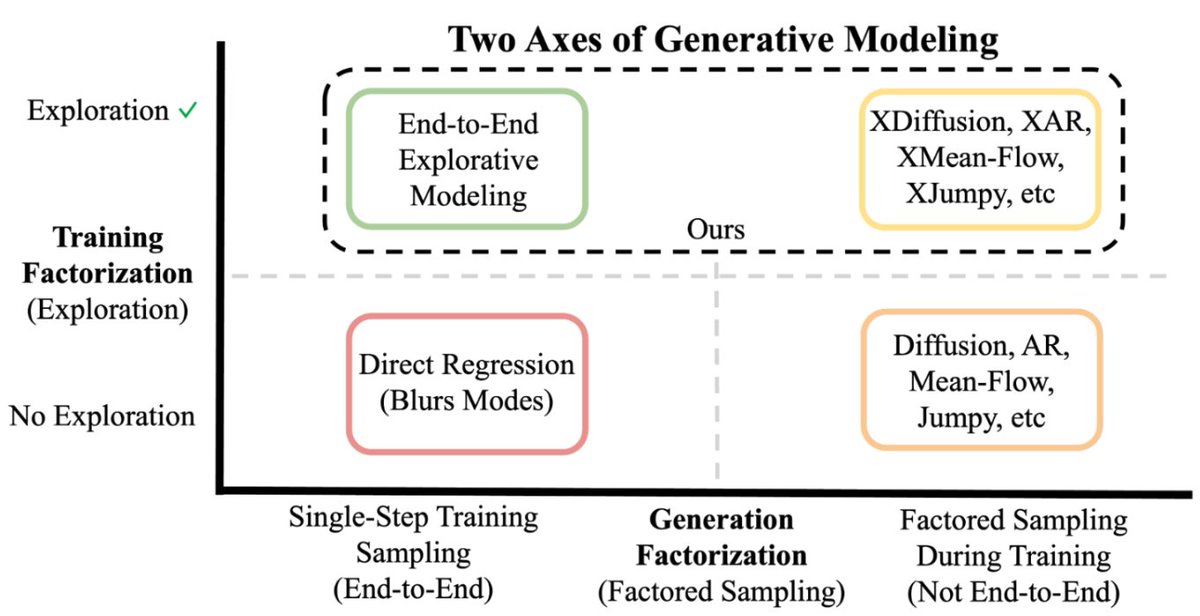
[9/N] How end-to-end can generative models actually become with exploration? There are two ways to handle the many-valid-outputs problem: decompose generation (existing approaches), or decompose training, which is Explorative Modeling. It turns out these are interchangeable, h
15.5K views · 66 likes · 5 reposts · 3 replies Open on X →
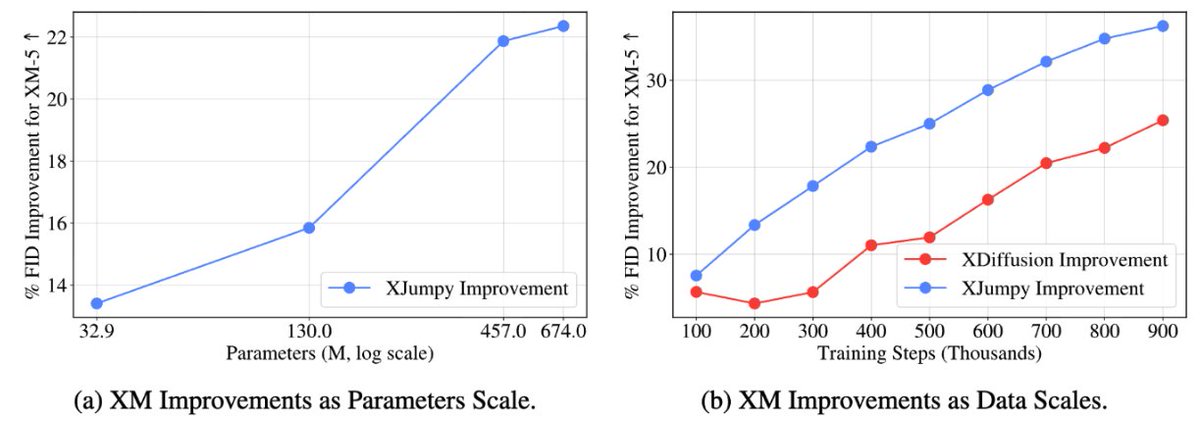
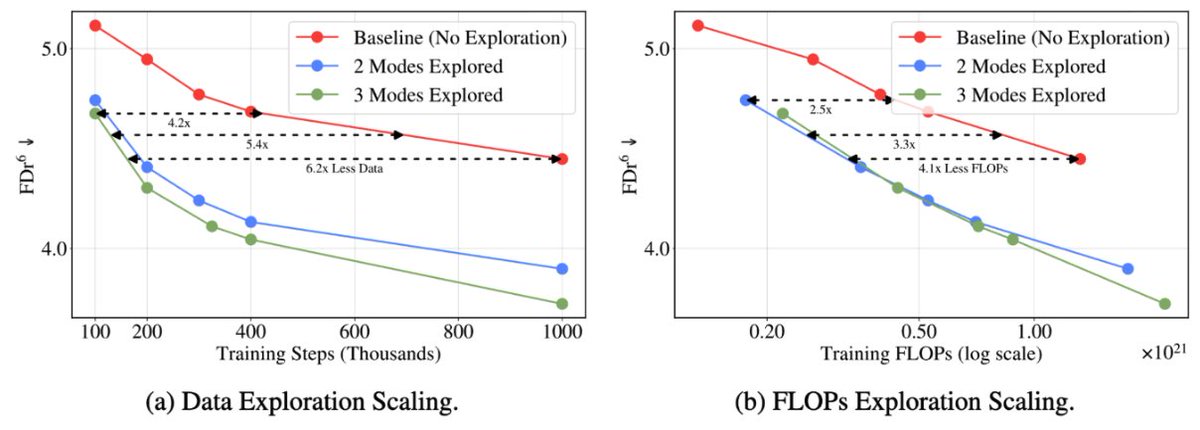
[6/N] How do gains from exploration change with scale? They grow. 7%→36% as data scales. 13%→23% as models scale. Efficiency gains more than doubled when we tripled compute. There's a cool reason for this. For the past decade we’ve scaled parameters, which set what a model htt
16.4K views · 81 likes · 5 reposts · 1 replies Open on X →
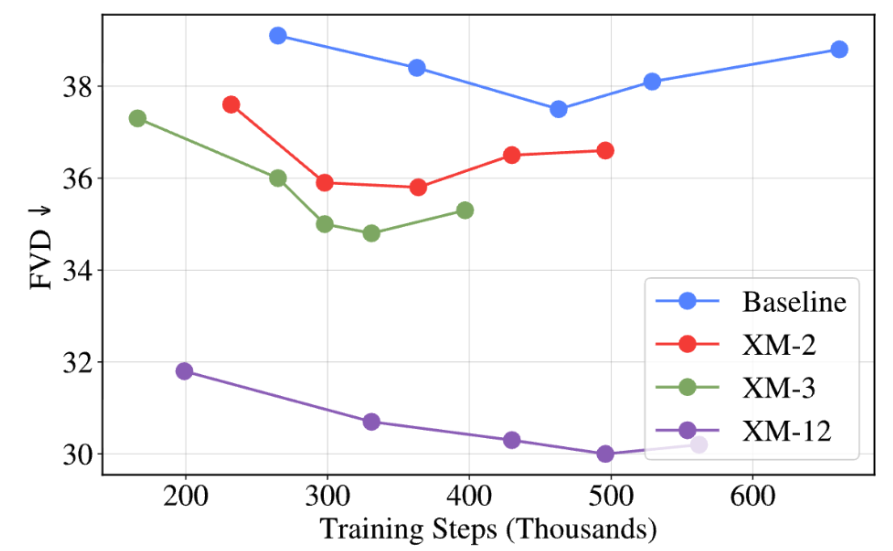
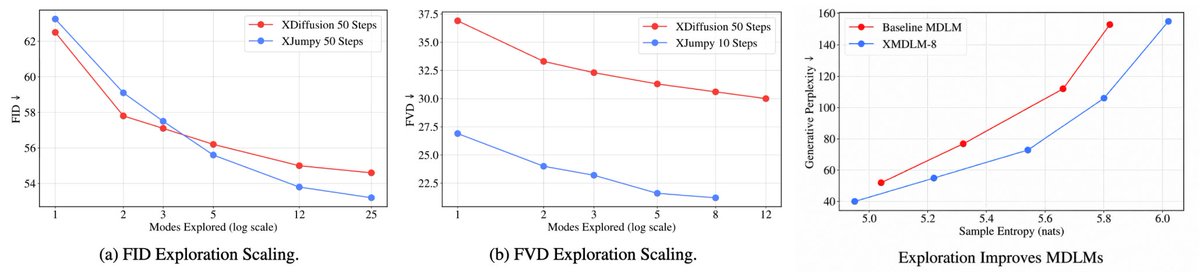
[7/N] Does this hold beyond images? We tested video generation and Masked Diffusion Language Models (MDLMs), alongside the image models from above. In all three, more exploration monotonically improved performance. Some video models improved by over 20%, and MDLMs improved http
15.6K views · 84 likes · 6 reposts · 1 replies Open on X →
[5/N] Exploration doesn't just enable end-to-end models, it turns out existing generative models may also need exploration... Breaking down generation doesn't always solve averaging, as each step's prediction can still face many valid outputs at once. Because of this, even ~SOTA
17.5K views · 93 likes · 4 reposts · 2 replies Open on X →
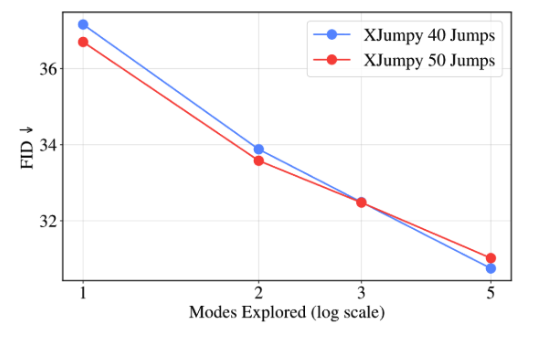
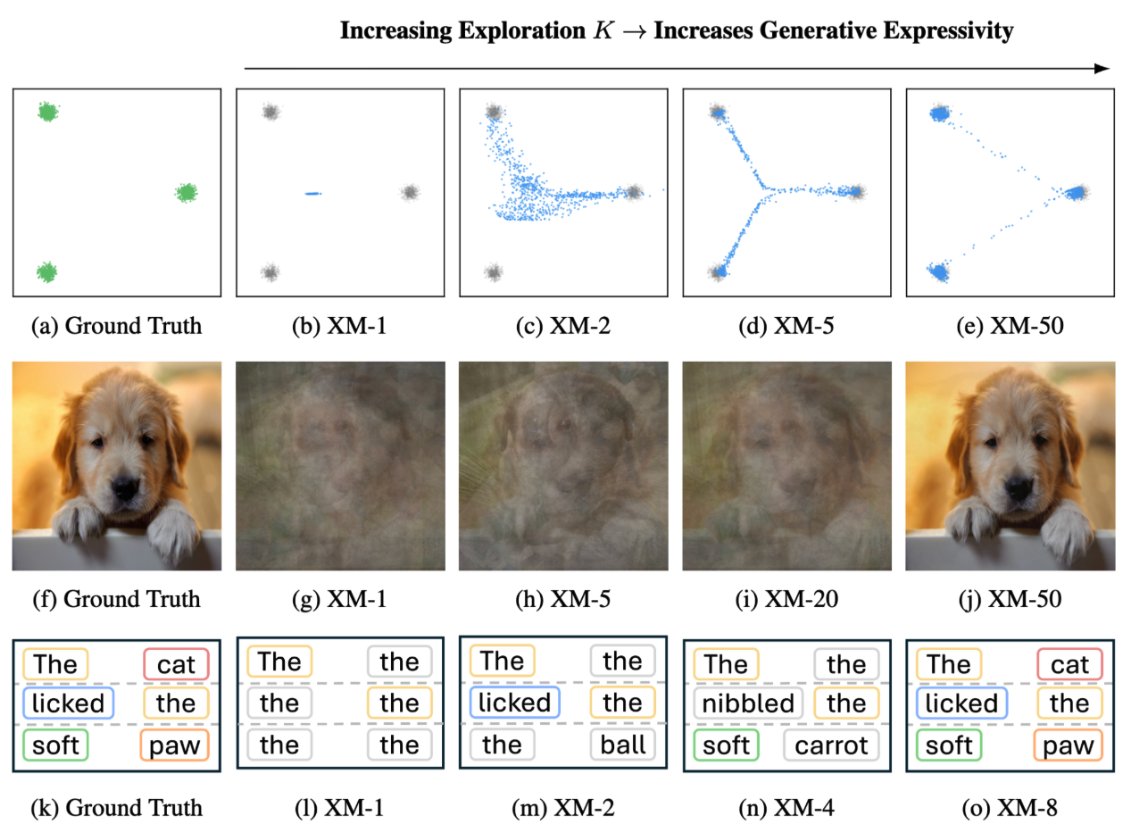
[4/N] What happens as models explore more? We trained fully end-to-end models (no breaking generation into steps) on 2D data, images, and text, varying only the amount of exploration K. At K=1 (no exploration), you get the averaging problem where models predict a single dot, a
19.9K views · 92 likes · 3 reposts · 1 replies Open on X →
[3/N] Can we avoid breaking down generation? Generative models only have two processes to decompose: generation and training. If we can’t decompose generation, the only thing left to decompose is training… So that's what we do. At each training step, the model generates K https
22.3K views · 119 likes · 7 reposts · 3 replies Open on X →
[2/N] How do existing generative models solve this problem? They break down generation into many small steps, so each step has essentially one right output and there is nothing to average. Autoregressive LLMs predict one token at a time. Diffusion denoises a little at a time. h
39.4K views · 109 likes · 6 reposts · 1 replies Open on X →
Project Page: https://t.co/rKTx0sZq2j [1/N] Why is generative modeling hard? "Generate a dog" has billions of valid outputs. So training a model to directly predict dog images gives you the average of them all, which is just a brown blur. Capturing all those valid outputs, htt
38K views · 131 likes · 9 reposts · 1 replies Open on X →
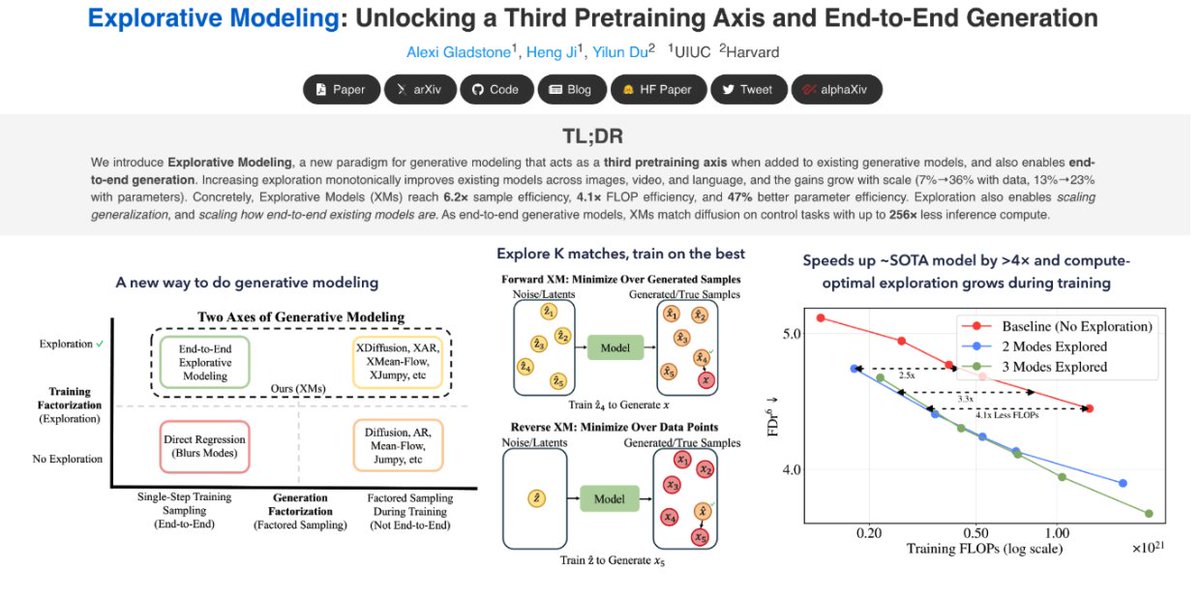
We discovered a third pretraining axis beyond parameters and data: exploration. Scaling exploration monotonically improves existing models across images/video/language, and unlocks end-to-end generation. In the simplest case, it's just a for loop. Introducing Explorative https
1.1M views · 2.8K likes · 318 reposts · 114 replies Open on X →

Frente a cuentas del mismo tamaño

13 publicaciones de los últimos 90 días, junto al rango de under 10K seguidores. alcance normal para su tamaño, reacción más débil que la mayoría.

Visualizaciones medianas16 381esta cuenta3 752mediana de under 10K
Alcance, %196.86%esta cuenta246.52%mediana de under 10K
Interacción, %0.53%esta cuenta1.41%mediana de under 10K
MétricaEsta cuentaMediana de under 10KProporción
Visualizaciones medianas por publicación16 3813 7524.37×
Alcance (visualizaciones ÷ seguidores)196.86%2.5× audience0.80×
Tasa de interacción0.53%1.41%0.38×

Otras cuentas de este rango →   Comparar con otra cuenta →   Cómo se construyen estas referencias →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

1.1M31 Jul
38K
39.4K
22.3K
19.9K
17.5K
15.6K
16.4K
15.5K
14.7K
15.8K
13.6K
7.1K

Last 13 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

0.30%31 Jul
0.37%
0.29%
0.58%
0.48%
0.57%
0.59%
0.53%
0.48%
0.51%
0.93%
1.32%
0.55%

Reactions — likes, reposts, replies and quotes — divided by views. Median for under 10K accounts is 1.41%.

What the audience does

Likes49.1%3 970 in total
Reposts4.8%388 in total
Replies1.8%145 in total
Bookmarks44.3%3 588 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

Cuentas similares