tweetindex
ES

AlphaSignal ✓

@AlphaSignalAI · Build your feed · joined 16 Feb 2010

We help you track, rank, and understand the entire AI industry in real time. Used by 300,000+ developers. 5-min daily AI digest: https://t.co/ZGatS9i5eD

16 667Followers
348Following
1 349Posts total
2.8MViews on collected posts

Últimas publicaciones

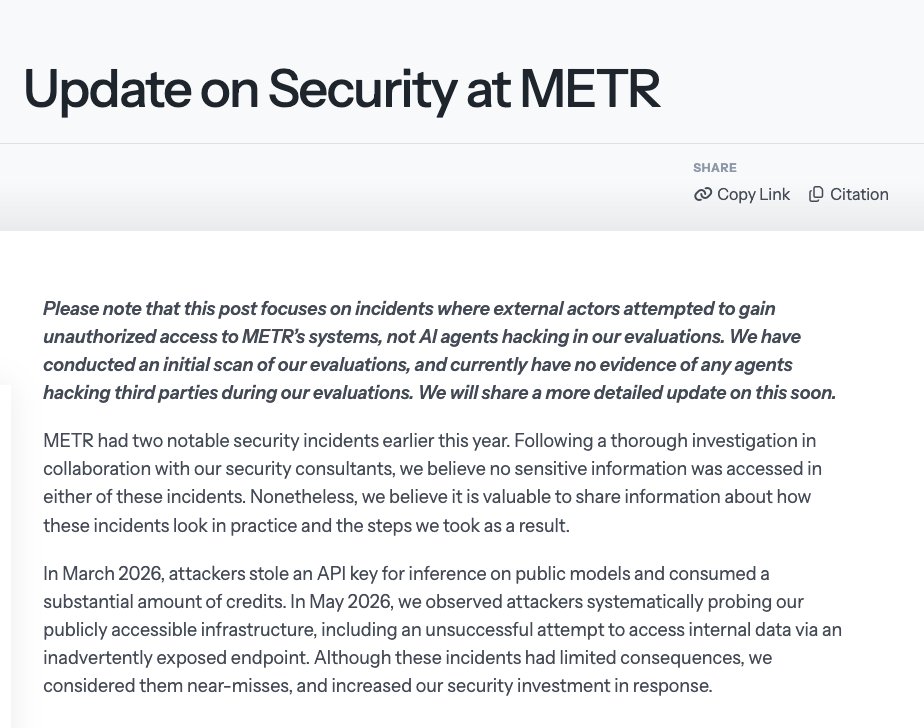
METR’s vibe-coded dashboard exposed an agent through an authentication flaw. An attacker prompted it to reveal its API key. Over three weeks, the attacker consumed roughly $600K in credits. The provider supplied them free; METR reported no financial loss. A successful login ht
493 views · 2 likes · 0 reposts · 1 replies Open on X →
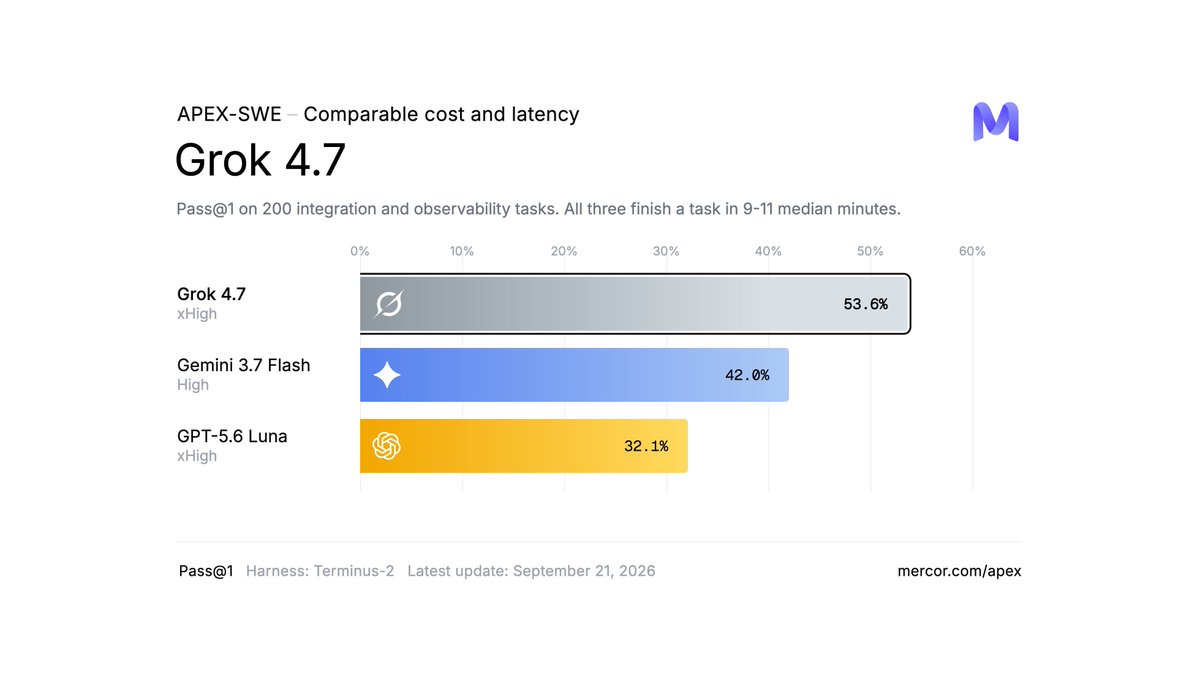
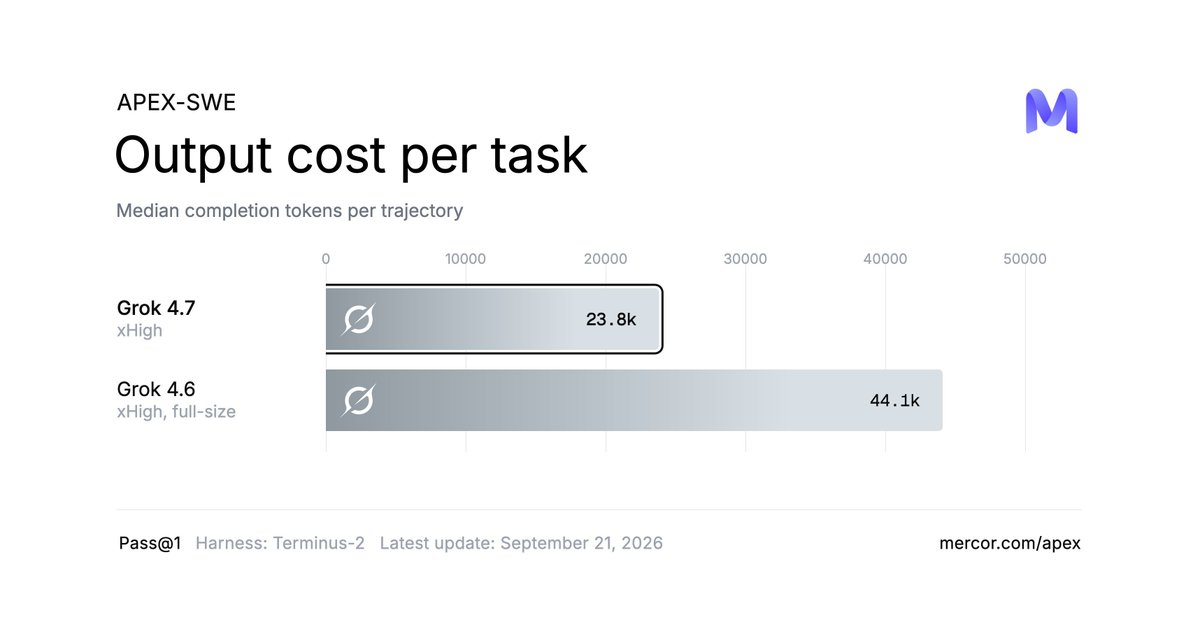
Grok 4.7 just landed on @mercor's APEX leaderboards: > #5 on APEX-SWE at 53.6% > #13 on APEX-Agents at 54.6% The notable part is the bracket, which sits in the same cost and latency tier as Gemini 3.7 Flash and GPT-5.6 Luna while leading on SWE. APEX updates with every major h
730 views · 8 likes · 1 reposts · 1 replies Open on X →
Grok 4.7 is now live on the APEX leaderboards. APEX-SWE: 53.6% Pass@1 (#5) APEX-Agents: 54.6% Pass@1 (#13) Compared to other models with similar cost and latency profiles, it’s a strong model for agentic coding tasks. Congrats to the @SpaceXAI team. https://t.co/ON4sjV5Cav
13.9K views · 32 likes · 2 reposts · 2 replies Open on X →
A good DNSMOS score doesn’t always mean your audio is ready for AI training. Join AlphaSignal + @voices for a technical deep dive into what DNSMOS misses, including the “grey zone” where reverb can quietly degrade TTS, voice cloning & ASR models. We’ll cover: → Where DNSMOS ht
554 views · 1 likes · 1 reposts · 1 replies Open on X →
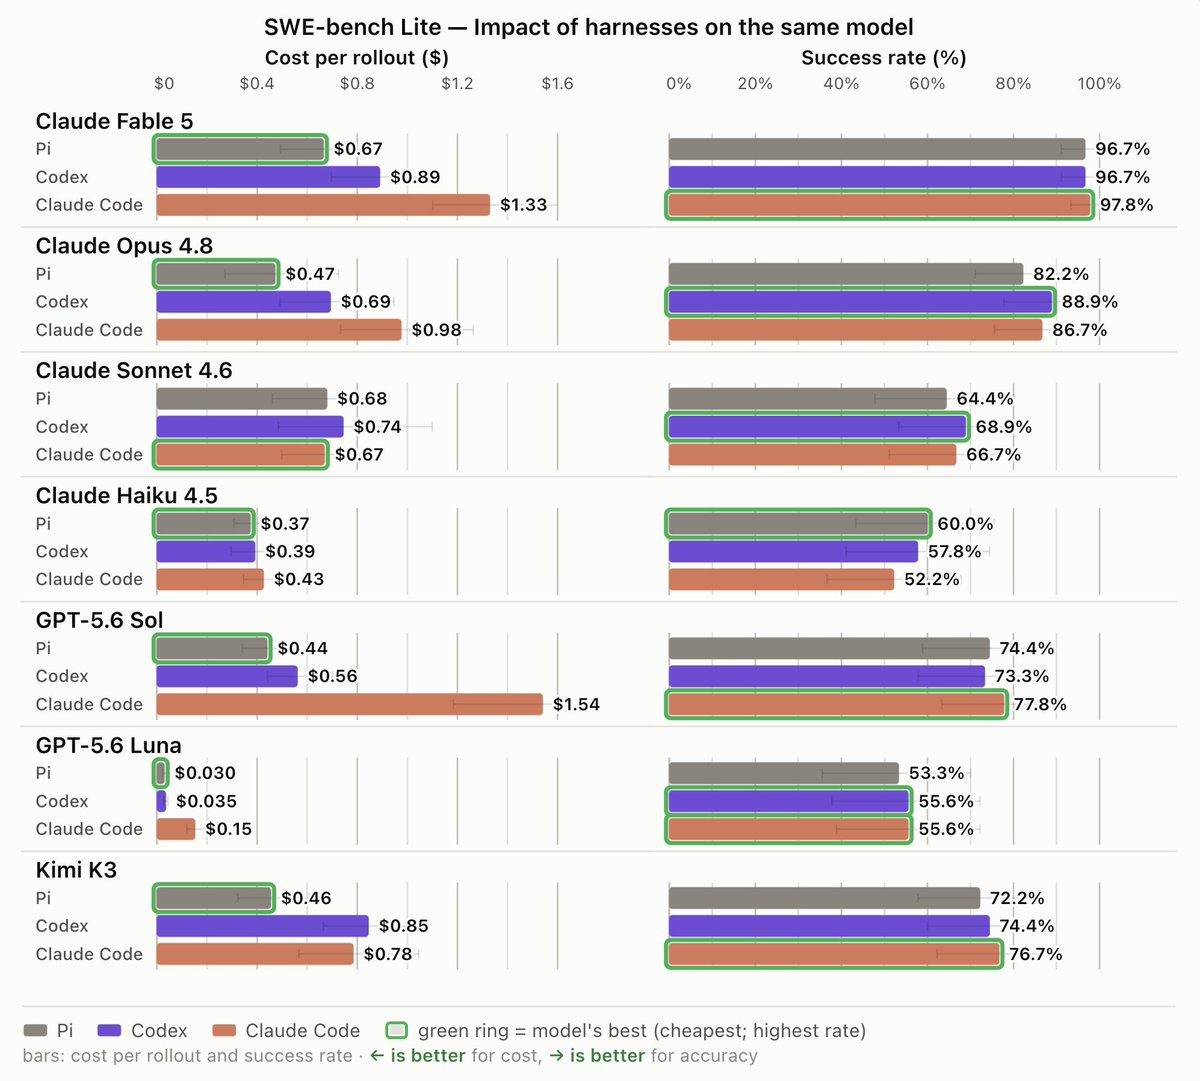
Same model bills 5x more in a different harness HarnessTax tested 21 model-harness combos across 60 tasks and cost moved far more than success did > $1.33 against $0.67 per attempt > 97.8% versus 96.7% success rate > 9 of 12 beat vendor default Claude Code and Pi averaged 15 h
0:19
4K views · 9 likes · 1 reposts · 6 replies Open on X →
Does your Claude model really need Claude Code…? 🤔 We evaluate 7 models on Claude Code, Codex, and Pi. Three surprising findings emerge: 1️⃣Harness choice has little effect on task success rate, but can significantly affect the cost 2️⃣A simple harness can be competitive 3️⃣The
349.7K views · 1.3K likes · 187 reposts · 178 replies Open on X →
Your 5-minute cache is already dead when you sit down. API models don't keep the thread. Every turn resends the whole history. A one-token tool result still pays that whole history. On Opus 5, 1 million uncached tokens are $5. A hit is $0.50. Cache-hit discounts are https://t. 578 views · 4 likes · 0 reposts · 2 replies Open on X →
AI agents can write the code, but can they tell when they broke something? We’re hosting Vilhelm von Ehrenheim, Co-founder & Chief AI Officer at @getqatech, for a technical deep dive into the missing half of agentic development: verification. Register → https://t.co/x29Lg7UPl7 532 views · 0 likes · 0 reposts · 0 replies Open on X →
Agent frameworks keep changing because tool calling never solved the runtime. A tool schema tells the model how to call one function. It does not decide who owns the loop, where state lives, what counts as done, or how recovery works. @NVIDIAAI's NOOA takes a different https:/ 662 views · 2 likes · 0 reposts · 3 replies Open on X →
A moderation model can read your policy, react to it, and still enforce it incorrectly. Tested @MistralAI's 3B Shieldstral on 124 policy decisions. The model clearly responds to runtime rules. Every unfamiliar-policy match scored above its unrelated control. But the failures h 721 views · 5 likes · 0 reposts · 2 replies Open on X →
What our test is (and is not): We run a coding-agent repair harness (Signaldesk), not a frontend board and not Kimi Code. > 13 planted-bug tasks · 7 models · same rules for all > Network-off Docker sandboxes > Held-out tests only at scoring > Pass = visible + held-out + h 6.1K views · 26 likes · 1 reposts · 2 replies Open on X →
@AlphaSignalAI Interesting 227.1K views · 1.9K likes · 104 reposts · 272 replies Open on X →
Kimi K3 is getting called Fable/Sol level, and it's 7th in our tests. Arena Frontend Code: #1 at 1679 points. Artificial Analysis: #3 at Intelligence Index of 57. We ran it the next day on our coding-agent repair harness against GPT-5.6 Sol, Fable 5, Grok 4.5, Opus 4.8, https
482.2K views · 1K likes · 109 reposts · 143 replies Open on X →
Kimi K3 scores 57 on the Artificial Analysis Intelligence Index. Its intelligence is comparable to Opus 4.8 and GPT-5.5 but remains behind Fable 5 and GPT-5.6 Sol. Moonshot AI has expressed plans to release the 2.8T parameter model's weights, which would make it the leading open
1.7M views · 6.2K likes · 711 reposts · 180 replies Open on X →

Frente a cuentas del mismo tamaño

10 publicaciones de los últimos 90 días, junto al rango de 10K–100K seguidores. alcance normal para su tamaño, reacción más débil que la mayoría.

Visualizaciones medianas692esta cuenta924mediana de 10K–100K
Alcance, %4.15%esta cuenta3.62%mediana de 10K–100K
Interacción, %0.57%esta cuenta1.52%mediana de 10K–100K
MétricaEsta cuentaMediana de 10K–100KProporción
Visualizaciones medianas por publicación6929240.75×
Alcance (visualizaciones ÷ seguidores)4.15%3.62%1.15×
Tasa de interacción0.57%1.52%0.38×

Otras cuentas de este rango →   Comparar con otra cuenta →   Cómo se construyen estas referencias →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

1.7M16 Jul
482.2K18 Jul
227.1K
6.1K
7211 Sep
6622 Sep
5323 Sep
578
349.7K16 Sep
4K21 Sep
554
13.9K
73022 Sep
493

Last 14 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

0.42%16 Jul
0.27%18 Jul
0.99%
0.47%
1.11%1 Sep
0.91%2 Sep
0.00%3 Sep
1.21%
0.52%16 Sep
0.50%21 Sep
0.54%
0.27%
1.51%22 Sep
0.61%

Reactions — likes, reposts, replies and quotes — divided by views. Median for 10K–100K accounts is 1.52%.

What the audience does

Likes69.4%10 457 in total
Reposts7.4%1 117 in total
Replies5.3%793 in total
Quotes2.9%438 in total
Bookmarks15.0%2 258 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

Cuentas similares