
Sebastian Ruder ✓
@seb_ruder · Berlin, Deutschland · joined 26 Sep 2014
Research Scientist @AIatMeta MSL • Ex @Cohere @GoogleDeepMind
98 517Followers
1 445Following
4 286Posts total
534.7KViews on collected posts
Últimas publicaciones
Buscando publicaciones nuevas…
We'll be organizing the Second Big Picture Workshop at #ACL2026.
This is a meta-workshop, which explores research narratives and how they connect with each other.
Our talks will feature multiple speakers that argue different positions of a topic.
https://t.co/SXTqzuNVkB
24K views · 58 likes
· 6 reposts · 6 replies
Open on X →

AI for science is one of the most promising directions of our time—but the lack of data remains an issue. Dunia is closing the gap between simulation and real-world validation for materials. I'm excited to see what new breakthroughs this will enable!
7.4K views · 26 likes
· 0 reposts · 2 replies
Open on X →
@seb_ruder Good to see that our previous work, Pariksha, is well acknowledged here as the most similar work and baseline.
56 views · 2 likes
· 0 reposts · 0 replies
Open on X →
This was a collaboration with @chenxi_jw and linguists at Meta.
Thanks to @guzmanhe and @pritish_yuvi for helping us get the project off the ground!
3.2K views · 10 likes
· 1 reposts · 0 replies
Open on X →
We release:
📂 MENLO dataset
⚙️ Evaluation framework + rubrics
📄 Judge/RM prompts
🔬 Benchmark for multilingual reward modeling
Paper: https://t.co/LKAy493nlU
Data: https://t.co/co8O5WOOKp https://t.co/4TegeRmzy0
 3.8K views · 6 likes
· 0 reposts · 1 replies
Open on X →
Key takeaways:
– Fine-grained LLM judges benefit from pairwise evaluation and structured rubrics
– RL-trained cross-lingual reward modeling is feasible and helpful
– MENLO pushes toward scalable, preference-aligned multilingual generation https://t.co/57kx5CaMs5
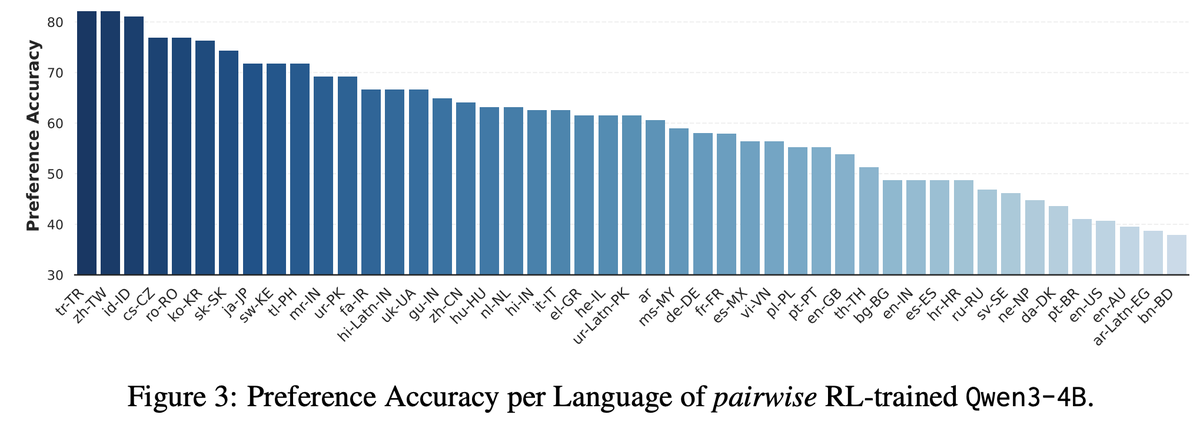 514 views · 4 likes
· 0 reposts · 1 replies
Open on X →
Reward models trained with MENLO can also be used generatively:
– As scoring functions for multilingual generation
– To improve proficiency and audience alignment in LLM outputs
Still: some human-model judgment divergences persist, LLM evaluators are overconfident about the ht
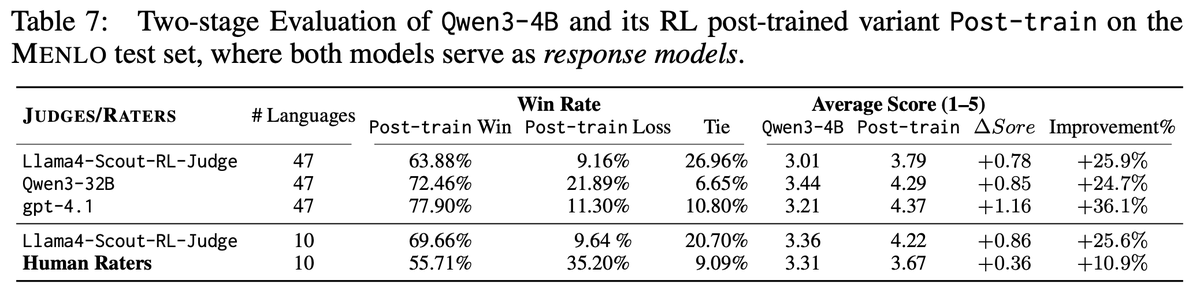 228 views · 3 likes
· 0 reposts · 1 replies
Open on X →
We explore:
🔁 Reinforcement learning
🏁 Reward shaping
🧠 Multi-task learning across languages/dimensions
→ These improve multilingual reward model quality and correlation with human judgments. https://t.co/wDudu4goxv
 279 views · 3 likes
· 0 reposts · 1 replies
Open on X →
We benchmark:
1. Zero-shot LLM judges
2. RL- & SFT-trained reward models
3. Human raters (gold)
Findings:
– Pairwise + rubric-based eval boosts zero-shot LLM judge performance
– But: gap with humans remains across languages https://t.co/UfSuaq2xdZ
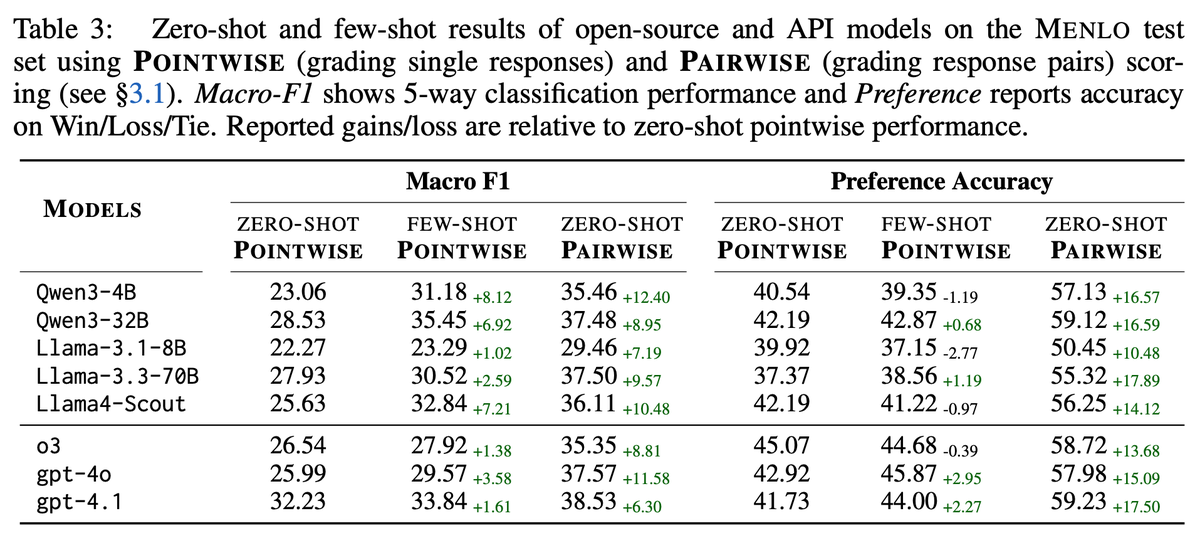 339 views · 5 likes
· 0 reposts · 1 replies
Open on X →
MENLO framework includes:
📊 6,423 human-labeled prompt-response preference pairs
🌐 47 language varieties
🧭 4 structured quality dimensions (fluency, tone, etc.)
✅ High inter-annotator agreement
⚖️ Pairwise judgments → better signal https://t.co/SW5nX5FwrX
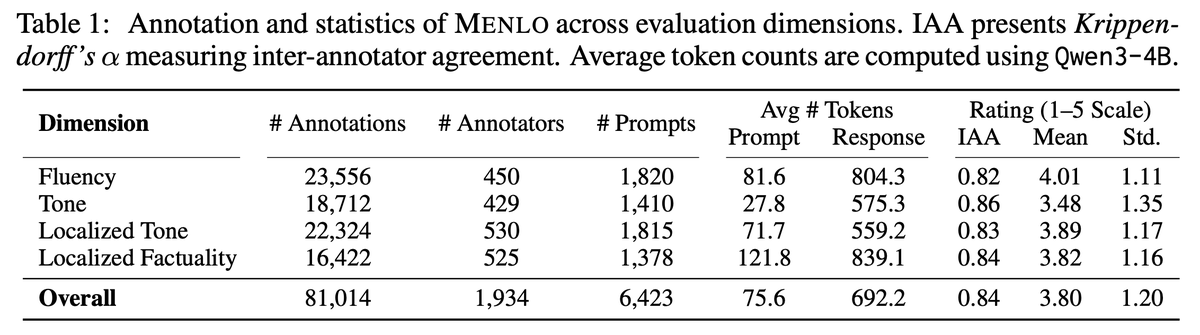 320 views · 5 likes
· 0 reposts · 1 replies
Open on X →
What makes a native speaker?
We go beyond fluency and consider a response’s factuality and tone with regard to the addressee and local context. We define 4 quality dimensions reflecting these attributes. https://t.co/nFqYRrA0nJ
 324 views · 5 likes
· 0 reposts · 1 replies
Open on X →
Multilingual LLMs ≠ Native speakers
Evaluating native-like generation across language varieties is hard, subjective, and inconsistent.
MENLO provides:
– A structured evaluation protocol
– Human preference data
– Model-based reward modeling for 47 languages https://t.co/zEBXaz
 432 views · 7 likes
· 0 reposts · 1 replies
Open on X →
🚨 New paper!
🌎 MENLO: From Preferences to Proficiency
We introduce a framework + dataset for evaluating and modeling native-like LLM response quality across 47 languages, inspired by audience design principles.
📄 Paper: https://t.co/LKAy493nlU
🤗 Data: https://t.co/co8O5WOOKp htt
 18.7K views · 105 likes
· 19 reposts · 6 replies
Open on X →
“Dunia” means Earth.
Our Goal is simple: To build the engine that discovers the materials of the future for this planet.
Because every leap in human history began with a material. https://t.co/rbT2ZpovJ3
446.3K views · 325 likes
· 46 reposts · 21 replies
Open on X →
1:29
I'll be at ACL 2025 in Vienna next week.
Say hi if you want to chat about multilinguality, LLM evaluation or doing research in industry.
You can also check out our ACL papers:
- M-RewardBench (Main): https://t.co/qCNxH7hU3M
- Global MMLU (Main): https://t.co/GR7rZ15Lg2
- Arabic
9.1K views · 122 likes
· 8 reposts · 5 replies
Open on X →
The Sparse Frontier
Efficient sparse attention methods are key to scale LLMs to long contexts. We conduct the largest-scale empirical analysis that answers:
1. 🤏🔍 Are small dense models or large sparse models better?
2. ♾️What is the maximum permissible sparsity per task?
3. htt
 19.7K views · 183 likes
· 31 reposts · 10 replies
Open on X →
Growth & engagement
How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.
Views per post
446.3K30 Sep
18.7K1 Oct
432
324
320
339
279
228
514
3.8K
3.2K
56
7.4K2 Oct
24K8 Oct
Last 14 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.
Engagement rate per post
0.09%30 Sep
0.73%1 Oct
1.85%
1.85%
1.88%
1.77%
1.43%
1.75%
0.97%
0.18%
0.34%
3.57%
0.38%2 Oct
0.30%8 Oct
Reactions — likes, reposts, replies and quotes — divided by views.
What the audience does
Likes61.3%869 in total
Reposts7.8%111 in total
Replies4.1%58 in total
Quotes2.3%32 in total
Bookmarks24.5%348 in total
Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.
Followers by day
17 Sep
Daily snapshots since 17 Sep 2026; the dashed line is the starting count.
Cuentas similares
 Peggy Noonan ✓
@Peggynoonannyc
197K followers
· 10.3K posts
 WhatsOnStage ✓
@WhatsOnStage
197K followers
· 86.8K posts
 Heather Childers ✓
@HeatherChilders
197K followers
· 30.7K posts
 Defence Turk ✓
@Defence_Turk
197K followers
· 45.5K posts
 Andy Staples ✓
@AndyStaples
197K followers
· 130.4K posts
 Gladd ✓
@Gladd
197K followers
· 27.7K posts
 【非公式】第五人格最新情報 ✓
@identityV_info
197K followers
· 6.2K posts
 Skye Hotwife ✓
@Skye_Hotwife
197K followers
· 1.7K posts