
Sihyun Yu
@sihyun_yu
phd @kaist_ai | ex @NVIDIAAI @GoogleAI @NYU_Courant
1 486Followers
809Following
301Posts total
178.5KViews on collected posts
Последние посты
Ищем новые посты…
@sihyun_yu The gap between human performance and MLLMs on tasks like these is a reminder that scaling doesn't automatically equal understanding. Progress in narrow benchmarks needs to translate to generalization across diverse visual contexts to be meaningful.
301 views · 2 likes
· 0 reposts · 0 replies
Open on X →

We're releasing everything: benchmark, eval code, and category labels!
🌐 https://t.co/I0lXS3WcNe
🤗 https://t.co/DlaA83veDx
💻 https://t.co/I9FLoNFuLQ
📄 https://t.co/X4f4xMf0IB
Huge thanks to amazing collaborators @ma_nanye @PinzhiHuang @hyunseok_i @shushengyang
692 views · 8 likes
· 1 reposts · 0 replies
Open on X →
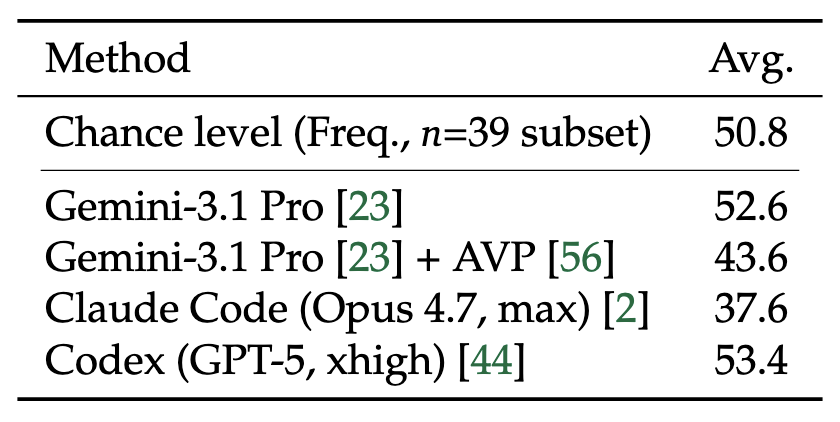
Do agentic frameworks help? We tried AVP (a video agent), Codex (GPT-5), and Claude Code (Opus 4.7). Each spends around 30 minutes per question writing visual reasoning code, and they still hover near chance level.
Coding agents tend to overthink, while video agents commit too h
 688 views · 7 likes
· 1 reposts · 2 replies
Open on X →
In the volleyball example, it correctly detects each ball touch by the white team, but assigns a new jersey number every time, even when the same player touches the ball repeatedly.
[9/11] https://t.co/SOunCsFC8h
 582 views · 6 likes
· 1 reposts · 1 replies
Open on X →
For example, in the shell game, the model often picks the wrong cup as the swapped one, and tends to assume a regular swap pattern even though the swaps are random.
[8/n] https://t.co/Fzi18TDTx5
 643 views · 6 likes
· 1 reposts · 1 replies
Open on X →
When do MLLMs fail?
By comparing thinking traces against the actual video, we identified three recurring failure modes:
1. Event recognition: misidentifying what happened (>50% of all errors).
2. Entity association: losing track of which entity (e.g. player/cup/object) is
647 views · 6 likes
· 0 reposts · 1 replies
Open on X →
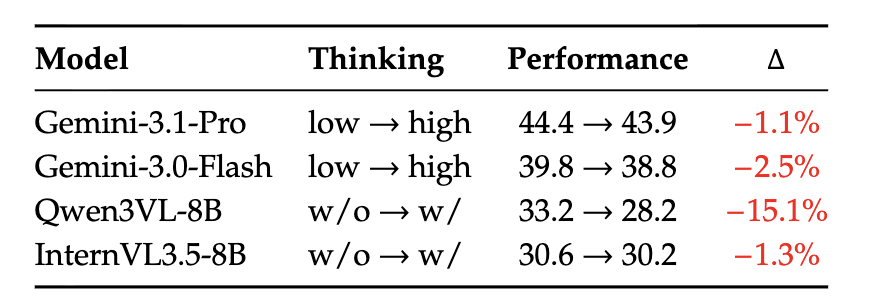
An interesting side finding: enabling "thinking" mode often hurts performance. Gemini-3.1 Pro drops from 44.4 to 43.9, and Qwen3VL-8B drops from 33.2 to 28.2 (a 15% relative drop).
When perception is flawed, more thinking just yields more confident hallucinations.
[6/11] https:
 777 views · 7 likes
· 2 reposts · 1 replies
Open on X →
The second hypothesis: maybe the bottleneck is visual perception, not reasoning.
We ran a small diagnostic. For a few simple Blender tasks where the visible state can be manually transcribed, we fed Gemini a per-frame text transcript instead of the video. Gemini, which struggles
 830 views · 8 likes
· 1 reposts · 1 replies
Open on X →
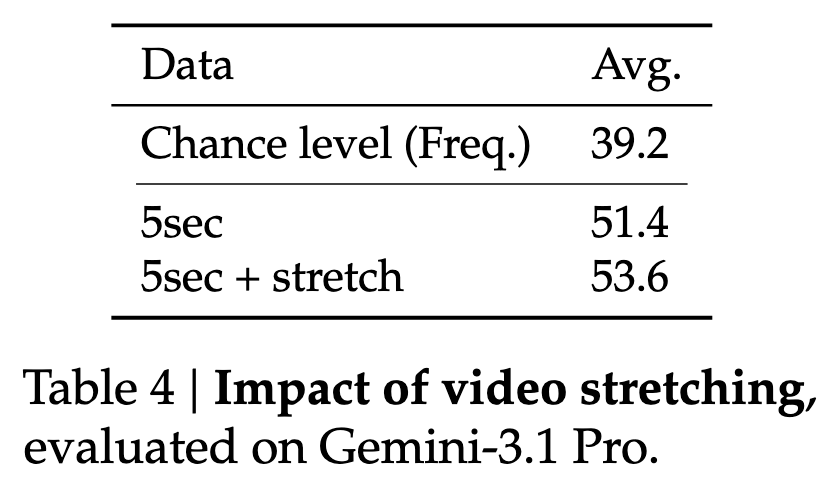
Why do MLLMs fail on VSTAT?
We considered two hypotheses. The first: maybe frame subsampling causes models to miss brief events. To test this, we temporally stretched the video so every event is fully visible at the model's frame rate. However, it showed only marginal https://t.
 962 views · 7 likes
· 1 reposts · 1 replies
Open on X →
The gap between humans and current MLLMs is large:
Humans: 90.5%Gemini-3.1 Pro: 44.4%Best open-source (LLaVA-OV-2-8B): 35.1%Frequency baseline: 37.8%
Strong performance on existing video benchmarks doesn't transfer to VSTAT.
[3/11] https://t.co/Ng1PRaer3R
 1.6K views · 11 likes
· 1 reposts · 1 replies
Open on X →
VSTAT consists of 834 videos and 1,500 questions, drawn from Blender-synthesized scenes, self-recorded clips, and YouTube videos.
Every task is designed so the answer can't be read off any keyframe or short segment. Models have to integrate events across the entire video.
[2/11]
 2K views · 8 likes
· 0 reposts · 1 replies
Open on X →
Can MLLMs actually track what's happening in a video?
Introducing VSTAT 🎯, our new benchmark for visual state tracking.
The tasks are simple: count cups, read typed words, count page flips. Humans solve them easily. MLLMs don't.
https://t.co/ZKqIDH5PcN
🧵 [1/11] https://t.co/Em
168.7K views · 248 likes
· 66 reposts · 11 replies
Open on X →
0:15
Growth & engagement
How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.
Views per post
168.7K3 Jun
2K
1.6K
962
830
777
647
643
582
688
692
301
Last 12 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.
Engagement rate per post
0.19%3 Jun
0.44%
0.81%
0.94%
1.20%
1.29%
1.08%
1.24%
1.37%
1.45%
1.30%
0.66%
Reactions — likes, reposts, replies and quotes — divided by views.
What the audience does
Likes58.2%324 in total
Reposts13.5%75 in total
Replies3.8%21 in total
Bookmarks24.6%137 in total
Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.
The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.
Похожие аккаунты
 aphex ✓
@0xaphex
3K followers
· 1.7K posts
 Olivier Maes
@olivierjmaes
3K followers
· 4.2K posts
 CoogTV ✓
@UHCoogTV
3K followers
· 5.3K posts
 Ramón Núñez Fernández
@RamonNunez81
3K followers
· 37.6K posts
 Freddy Montiri
@freddy_montiri
3K followers
· 23.9K posts
 Chef Israel ✓
@ChefIsraelA3
3K followers
· 1.3K posts
 Sirio Merenda
@siriomerendax
3K followers
· 116 posts
 Eric_Claxon
@EricClaxon_
3K followers
· 23.5K posts