tweetindex
TH

Joachim Schork ✓

@JoachimSchork · Germany · joined 05 Aug 2018

Data Science Education & Consulting

23 781Followers
86Following
9 348Posts total
5.9KViews on collected posts

โพสต์ล่าสุด

Regression imputation is a widely used method for handling missing data, leveraging relationships between variables to estimate missing values. However, it faces significant challenges when applied to heteroscedastic data, where the variance of the dependent variable changes http
685 views · 11 likes · 0 reposts · 0 replies Open on X →
Missing data imputation is an important step to reduce bias and improve the quality of your analysis. However, the process should not stop once the imputed values are created. It is just as important to check the quality of the imputations. There are many numerical and graphical
1K views · 25 likes · 3 reposts · 0 replies Open on X →
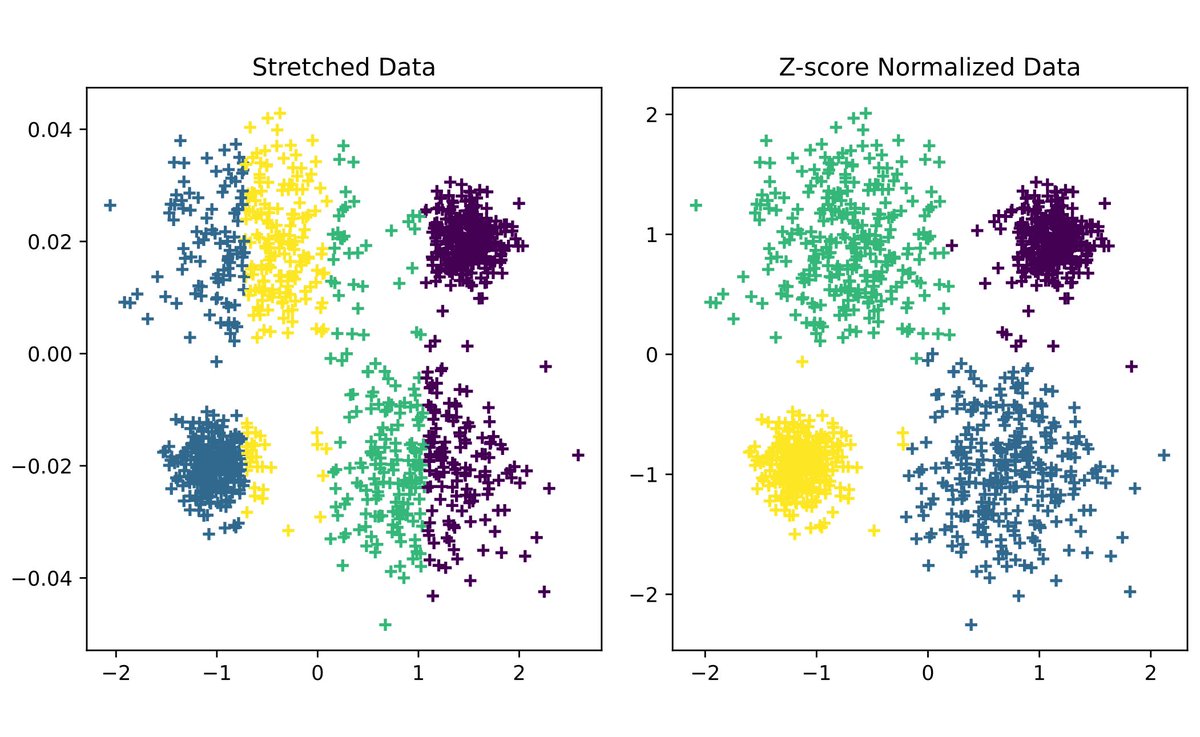
When variables have very different scales, many algorithms can become biased toward features with larger ranges. Feature scaling ensures all variables contribute equally by putting them on comparable scales, making your analysis or model more balanced and interpretable. Why use
1.3K views · 34 likes · 8 reposts · 0 replies Open on X →
@JoachimSchork @JuanluCaba_Unex Nella scheda riassuntiva visualizzata, sezione 5, c'è un refuso di calcolo che riporta R1 = 52 e R2 = 36, ma la procedura matematica corretta applicata ai dati riportati nel testo produce R1 = 84 e R2 = 52.) 8 views · 0 likes · 0 reposts · 0 replies Open on X →
@JoachimSchork @JuanluCaba_Unex Getting Started with NNS: Comparing Distributions https://t.co/B4mylcT6FP 19 views · 1 likes · 0 reposts · 0 replies Open on X →
The Mann–Whitney U test is a useful method for comparing two independent groups when the assumptions of a t-test are not met. Ranking the observations makes it possible to assess group differences without relying on normally distributed data. Thanks @JuanluCaba_Unex for sharing 2.8K views · 74 likes · 16 reposts · 2 replies Open on X →
After 3 years, 4 months & 2 days of hard work, I have just hit a very big milestone: I have just published the 1000th tutorial on the Statistics Globe website!!! https://t.co/sT4lgmC4st Thank you for being part on the way to this achievement! #RStats #Statistics #DataScience 0 views · 415 likes · 72 reposts · 28 replies Open on X →

เทียบกับบัญชีขนาดเดียวกัน

6 โพสต์จาก 90 วันที่ผ่านมา เทียบกับช่วง 10K–100K ผู้ติดตาม การเข้าถึงปกติสำหรับขนาดนี้ แต่การตอบสนองแรงกว่าส่วนใหญ่.

ยอดดูมัธยฐาน843บัญชีนี้924ค่ามัธยฐานของ 10K–100K
การเข้าถึง, %3.54%บัญชีนี้3.62%ค่ามัธยฐานของ 10K–100K
การมีส่วนร่วม, %2.99%บัญชีนี้1.52%ค่ามัธยฐานของ 10K–100K
ตัวชี้วัดบัญชีนี้ค่ามัธยฐานของ 10K–100Kอัตราส่วน
ยอดดูมัธยฐานต่อโพสต์8439240.91×
การเข้าถึง (ยอดดู ÷ ผู้ติดตาม)3.54%3.62%0.98×
อัตราการมีส่วนร่วม2.99%1.52%1.97×

บัญชีอื่นในช่วงนี้ →   เปรียบเทียบกับบัญชีอื่น →   ค่าอ้างอิงเหล่านี้คำนวณอย่างไร →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

2.8K23 Sep
19
8
1.3K
1K24 Sep
685

Last 6 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

3.24%23 Sep
5.26%
0.00%
3.19%
2.80%24 Sep
1.61%

Reactions — likes, reposts, replies and quotes — divided by views. Median for 10K–100K accounts is 1.52%.

What the audience does

Likes58.9%145 in total
Reposts11.0%27 in total
Replies0.8%2 in total
Bookmarks29.3%72 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

บัญชีที่คล้ายกัน