tweetindex
TH

Xidulu

@xidulu

Xi Wang, Full-stack Bayesian, ECNU, UMass CICS, JHU CS, Fan of U-Shape. Previously MSR Cambridge, Netflix Research

1 094Followers
881Following
1 666Posts total
307.4KViews on collected posts

โพสต์ล่าสุด

@xidulu @JohnCLangford Spiritually very similar to ParaRNN, w.r.t. approximating full sequential dependence with a constant number of sequential parallel operations. I like this project a lot and will maybe write an article on it https://t.co/hAw7uFvUkN https://t.co/XcA6K32AIm 2.2K views · 18 likes · 1 reposts · 2 replies Open on X →
8/ Lastly, deeply grateful to the members of the AI Frontiers team for their invaluable support and feedback: @ZhengZhan13 @jackcai1206 @yingfan_bot @Tea_Pearce 2.3K views · 29 likes · 0 reposts · 2 replies Open on X →
7/ In summary, - We utilize the sequential nature of the decoding process to squeeze in richer feedback information (continuous hidden state v.s. discrete token) - We proposed a way to use more FLOPs to boost performance w/o increasing tokens / model size: Better data efficiency! 2.5K views · 35 likes · 1 reposts · 1 replies Open on X →
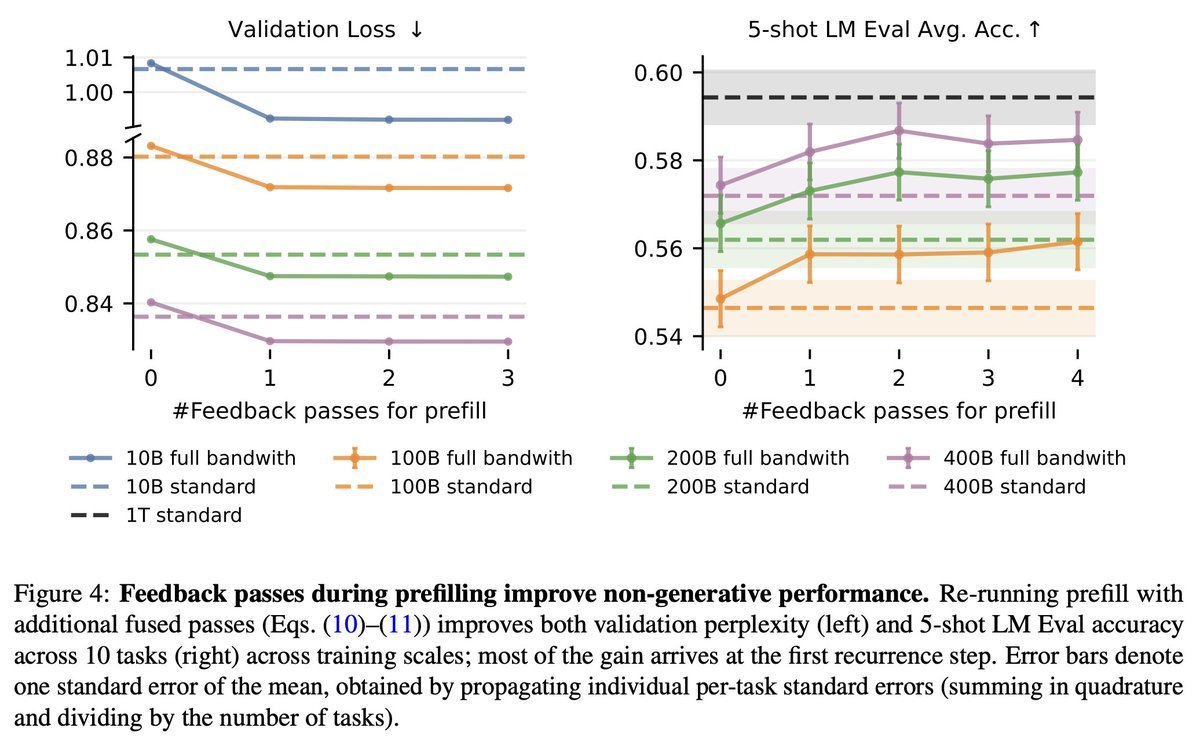
5/ The extra %30 flops spent at training time not only unlocks a new way of decoding, it also enables test-time scaling, where you use multi-pass prefilling for boosting validation loss and LM Eval performance https://t.co/KfAEdPTqf7
3.1K views · 35 likes · 1 reposts · 1 replies Open on X →
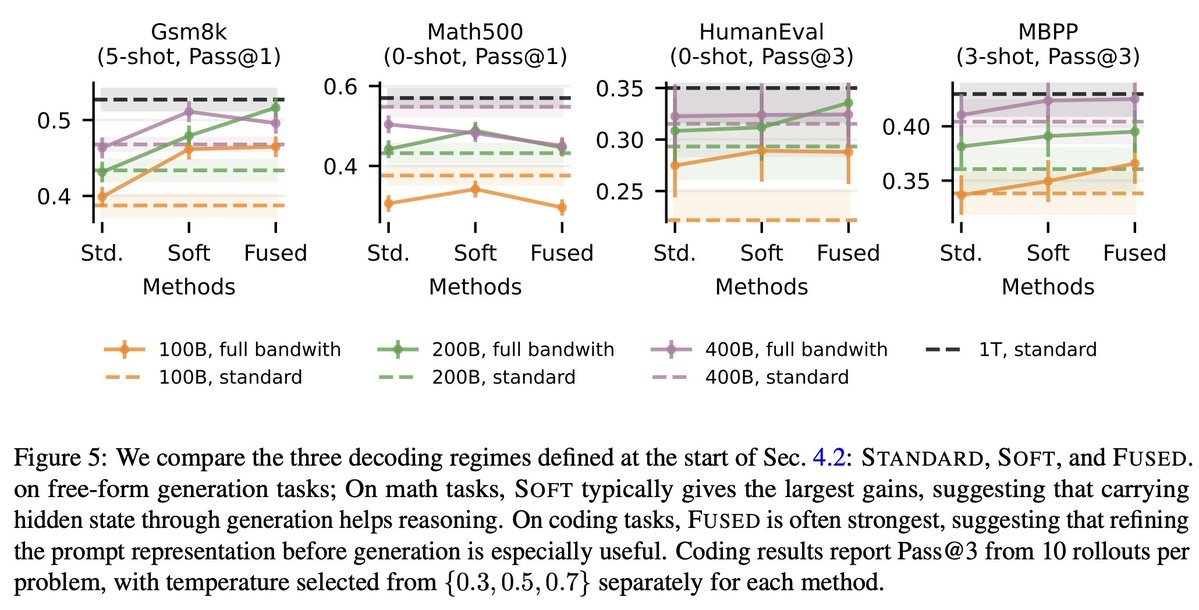
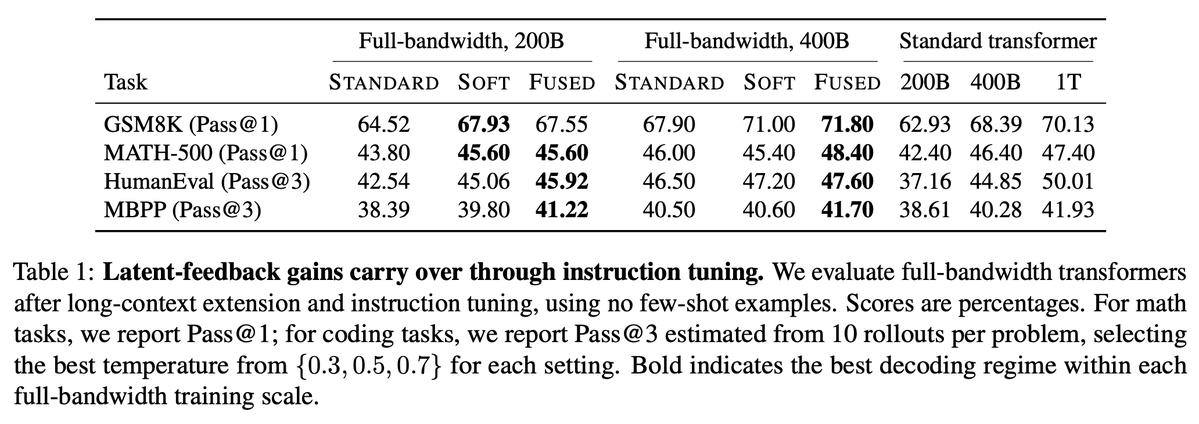
6/ Of course, models trained this way can perform - (Soft, free) Latent feedback decoding - (fused) Double prefill + soft decoding The extra 30% FLOPs spent at training time translate to free-form generation performance comparable with models trained with 2x the FLOPs https://t.c
6.6K views · 36 likes · 2 reposts · 1 replies Open on X →
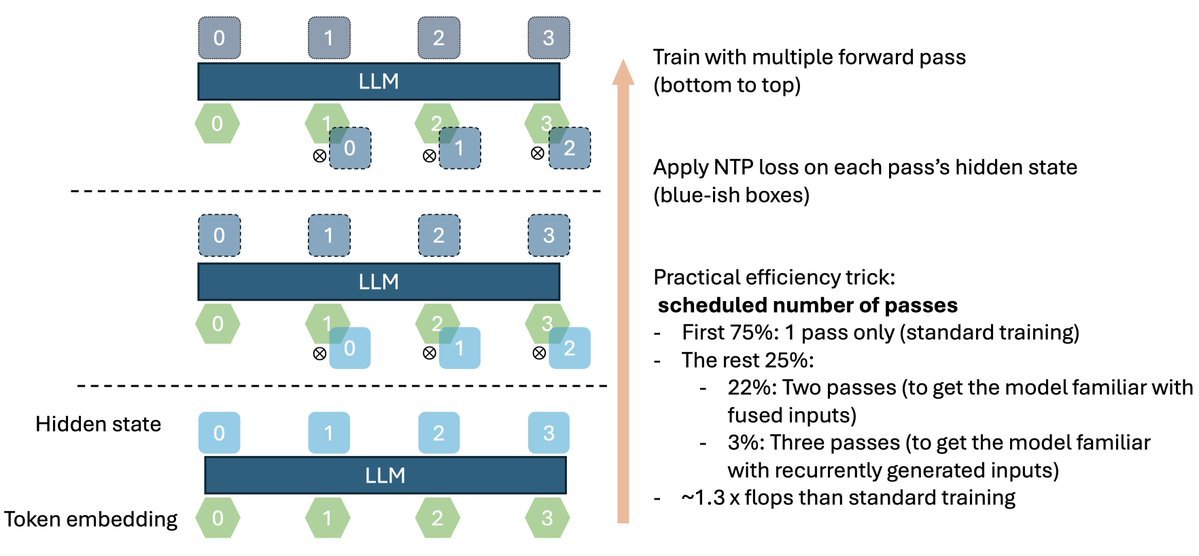
4/ Training takes extra flops: We need multi forward passes to teach the model to understand "embedding hidden state fusion" type of inputs. Luckily, you don't need to "loop" every iteration; introducing the "loops" progressively later on in the training still works! https://t.co
6K views · 41 likes · 1 reposts · 1 replies Open on X →
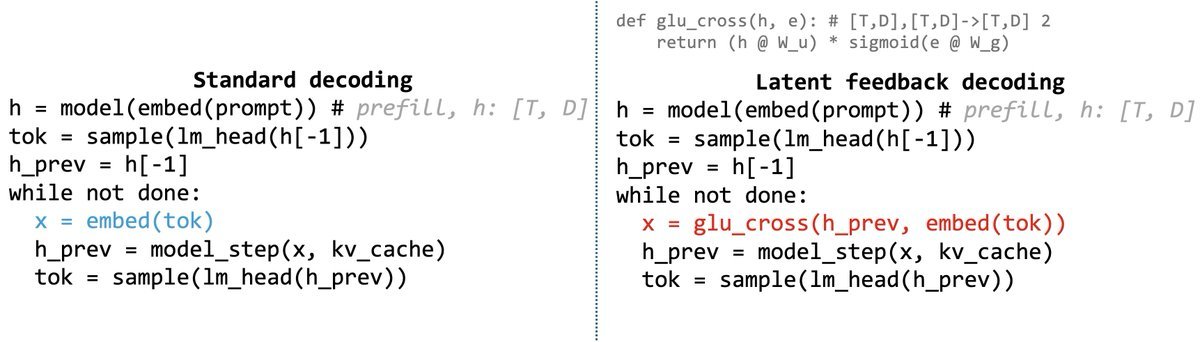
3/ Latent feedback decoding is free at inference time since the top layer hidden state is there anyway to perform decoding, the only extra overhead is the fusing operation, which only has two matmul https://t.co/hvZoSredap
4.9K views · 40 likes · 1 reposts · 1 replies Open on X →
2/ Our approach (latent feedback decoding) unlocks the ** full bandwidth ** of the transformer: - Dense attention gives full visibility over past positions - Our approach enhances the bandwidth vertically: It exposes past information across *depth* to the current layer/position h
12.6K views · 69 likes · 5 reposts · 1 replies Open on X →
1/ Sharing a new, interesting project I did during my internship at Microsoft AI Frontiers w/ @JohnCLangford TL;DR: At decoding time, we feed **previous hidden state** into the input together with token embedding, and it boosts performance for free. https://t.co/za3cZ4UwWV 267.1K views · 734 likes · 109 reposts · 16 replies Open on X →

เทียบกับบัญชีขนาดเดียวกัน

9 โพสต์จาก 90 วันที่ผ่านมา เทียบกับช่วง under 10K ผู้ติดตาม แสดงในวงกว้าง แต่มีผู้ชมตอบสนองน้อย.

ยอดดูมัธยฐาน4 912บัญชีนี้4 175ค่ามัธยฐานของ under 10K
การเข้าถึง, %448.99%บัญชีนี้250.82%ค่ามัธยฐานของ under 10K
การมีส่วนร่วม, %0.85%บัญชีนี้1.41%ค่ามัธยฐานของ under 10K
ตัวชี้วัดบัญชีนี้ค่ามัธยฐานของ under 10Kอัตราส่วน
ยอดดูมัธยฐานต่อโพสต์4 9124 1751.18×
การเข้าถึง (ยอดดู ÷ ผู้ติดตาม)4.5× audience2.5× audience1.79×
อัตราการมีส่วนร่วม0.85%1.41%0.61×

บัญชีอื่นในช่วงนี้ →   เปรียบเทียบกับบัญชีอื่น →   ค่าอ้างอิงเหล่านี้คำนวณอย่างไร →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

267.1K11 Aug
12.6K
4.9K
6K
6.6K
3.1K
2.5K
2.3K
2.2K

Last 9 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

0.33%11 Aug
0.61%
0.86%
0.73%
0.60%
1.18%
1.46%
1.32%
0.97%

Reactions — likes, reposts, replies and quotes — divided by views. Median for under 10K accounts is 1.41%.

What the audience does

Likes53.0%1 037 in total
Reposts6.2%121 in total
Replies1.3%26 in total
Quotes1.7%34 in total
Bookmarks37.7%737 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

บัญชีที่คล้ายกัน