
Jinhyuk Lee
@leejnhk
944Followers
366Following
106Posts total
93.3KViews on collected posts
Son gönderiler
Yeni gönderiler aranıyor…
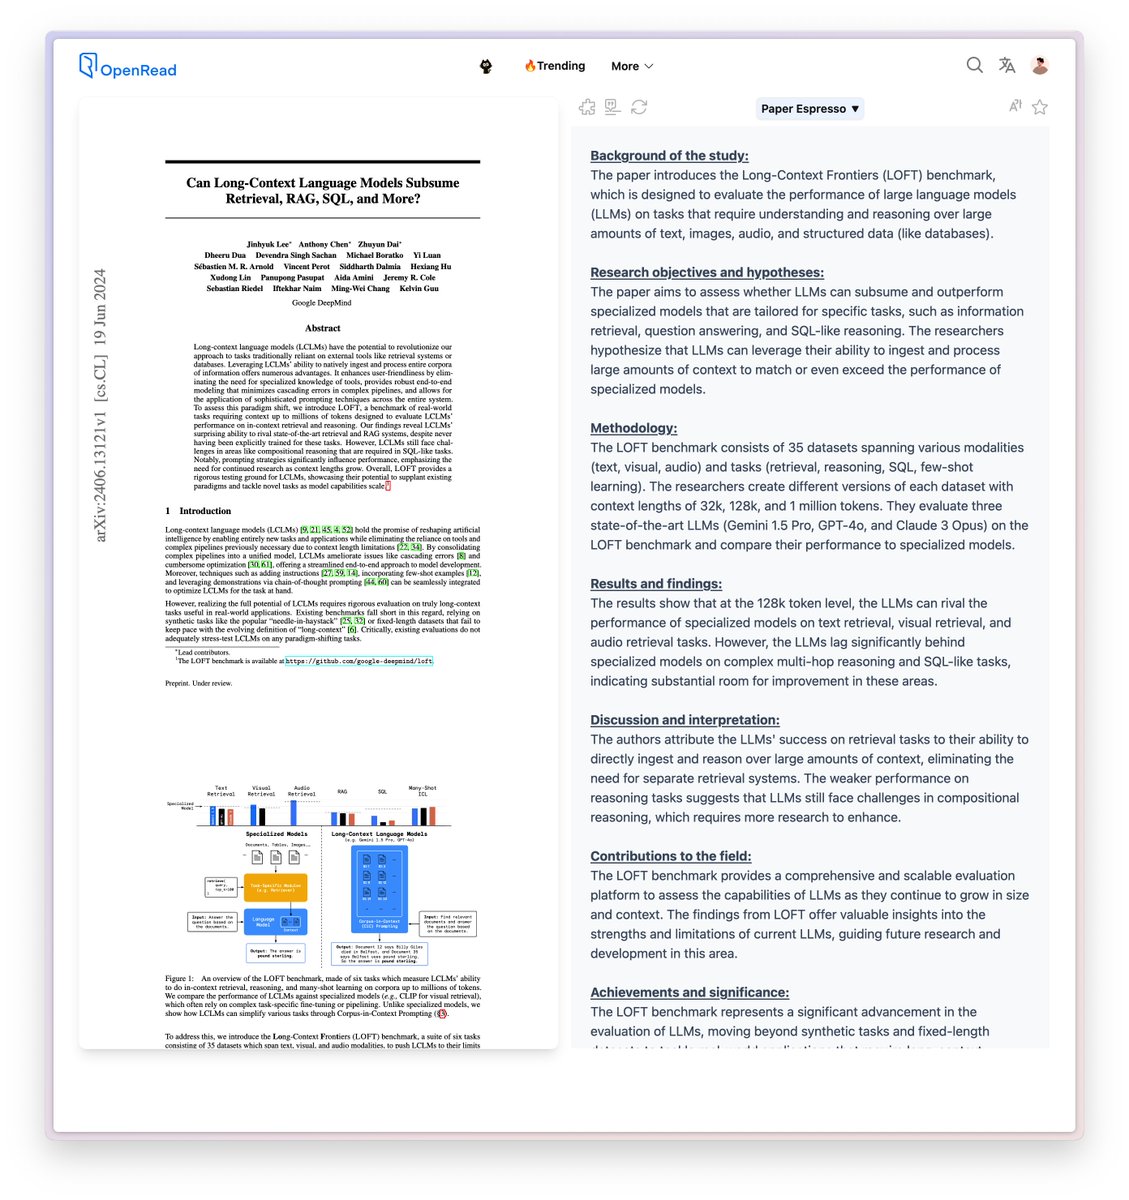
@leejnhk @GoogleDeepMind @GoogleAI The results show that at the 128k token level, the LLMs can rival the performance of specialized models on text retrieval, visual retrieval, and audio retrieval tasks. However, the LLMs lag significantly behind specialized models on complex mult
 163 views · 1 likes
· 0 reposts · 0 replies
Open on X →
Check out our paper for more details on the LOFT benchmark and the CiC prompting! In our paper, we also detail interesting ablation studies for the CiC prompting.
Paper: https://t.co/FFyI0rMCqw
Data: https://t.co/6JPfRIvR0i
1K views · 12 likes
· 2 reposts · 1 replies
Open on X →
This was an amazing collaboration by:
@leejnhk @_anthonychen @ZhuyunDai @ddua17 @Devendr06654102 @MichaelBoratko @YiLuan9 @seba1511 @vincentperot @siddalmia05 @Hexiang_Hu @Xudong_Lin_AI @IcePasupat @amini_aida @jeremy_r_cole @riedelcastro @IftekharNaim @mchang21 @kelvin_guu
888 views · 9 likes
· 0 reposts · 0 replies
Open on X →
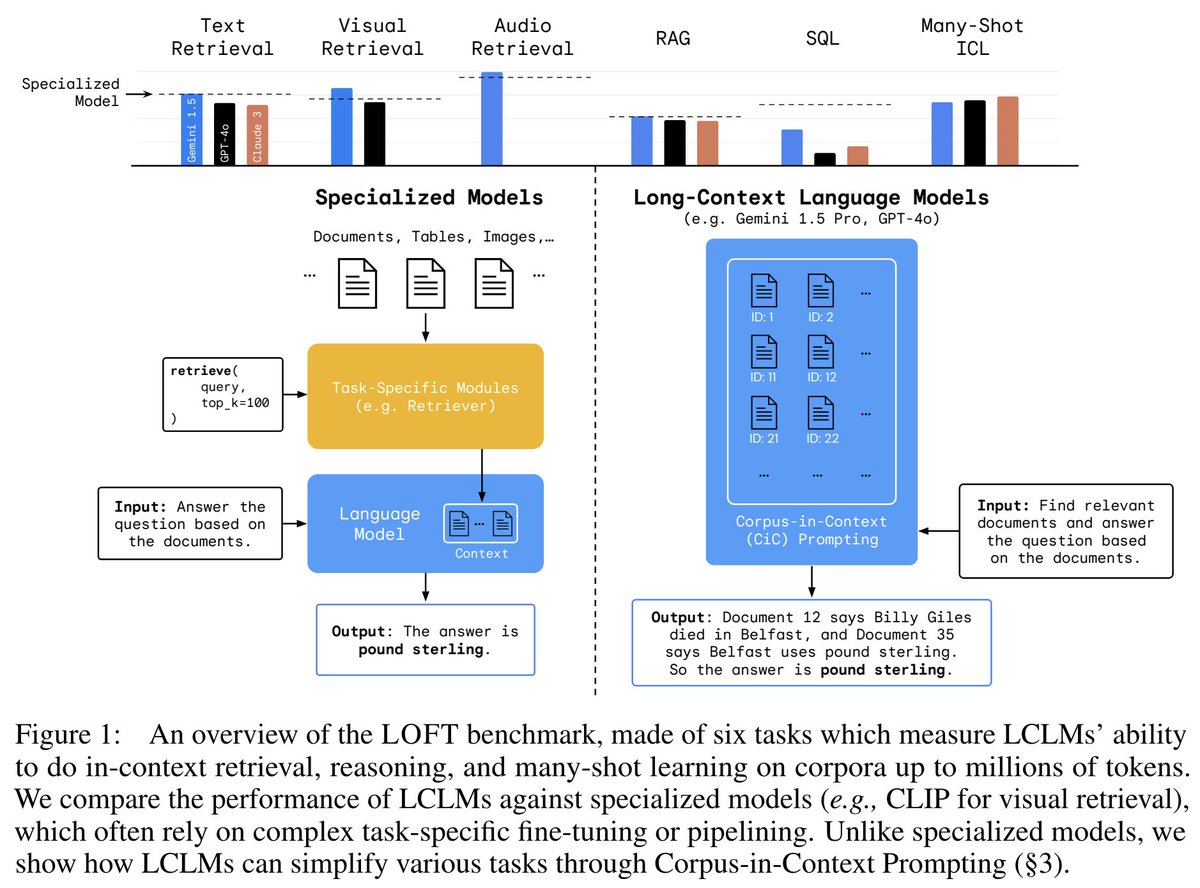
Our findings show that LCLMs can already achieve retrieval performance comparable to specialized systems like Gecko and CLIP. However, challenges remain in areas like multi-hop compositional reasoning. https://t.co/mHlmDVZfWv
 1.1K views · 12 likes
· 1 reposts · 1 replies
Open on X →
LOFT is a massive benchmark evaluating LCLMs on 30+ real-world retrieval & reasoning datasets across text, image, video, & audio. LOFT supports sequence lengths up to 1 million tokens (and possibly more!). https://t.co/nLbXmA5sWK
 1.7K views · 12 likes
· 1 reposts · 1 replies
Open on X →
To perform corpus-grounded reasoning, we introduce Corpus-in-Context prompting, which seamlessly integrates a corpus, instructions, and few-shot examples for LOFT tasks. Prompting strategies significantly influence LCLM performance, highlighting the need for continued research. h
 1.3K views · 11 likes
· 2 reposts · 1 replies
Open on X →
Can long-context language models (LCLMs) subsume retrieval, RAG, SQL, and more?
Introducing LOFT: a benchmark stress-testing LCLMs on million-token tasks like retrieval, RAG, and SQL. Surprisingly, LCLMs rival specialized models trained for these tasks!
https://t.co/FFyI0rMCqw
 87.1K views · 219 likes
· 53 reposts · 8 replies
Open on X →
Growth & engagement
How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.
Views per post
87.1K21 Jun
1.3K
1.7K
1.1K
888
1K
16323 Jun
Last 7 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.
Engagement rate per post
0.32%21 Jun
1.09%
0.84%
1.22%
1.01%
1.50%
0.61%23 Jun
Reactions — likes, reposts, replies and quotes — divided by views.
What the audience does
Likes58.4%276 in total
Reposts12.5%59 in total
Replies2.5%12 in total
Bookmarks26.6%126 in total
Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.
The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.
Benzer hesaplar
 Chuu 🇨🇴 ~ live2d art / rigg ✓
@ChuChanChel
1.9K followers
· 1.6K posts
 El Hombre ✓
@prittyflako
1.9K followers
· 10.4K posts
 @Bihari Babu@ ✓
@BIHARIBABU94
1.9K followers
· 130.7K posts
 Jill Bearup
@JillBearup
1.9K followers
· 548 posts
 Boom Boom SKOL
@BoomBoomSKOL
1.9K followers
· 23.1K posts
 Dawson's Creek-Shitter ✓
@CreekshitinDaws
1.9K followers
· 25.6K posts
 Scene World Magazine ✓
@Scene_World
1.9K followers
· 1.3K posts
 alob 𝓰𝓻𝓸𝔂𝓹𝓮𝓻
@hallofbee
1.9K followers
· 2.6K posts