tweetindex
ES

FAR.AI ✓

@farairesearch · Berkeley, California · joined 08 Feb 2023

Frontier alignment research to ensure the safe development and deployment of advanced AI systems.

21 633Followers
25Following
1 185Posts total
39.8KViews on collected posts

Últimas publicaciones

Tune in at 3 pm ET today: our co-founder and CEO @ARGleave joins the "Panel of Panels: Building a Global AI Evidence Base" at Digital Cooperation Day, part of the 81st UN General Assembly, alongside @Yoshua_Bengio, @mariaressa, and others working to strengthen the evidence base 1.1K views · 11 likes · 1 reposts · 1 replies Open on X →
@farairesearch Vấn đề là nếu AI nói điều con người muốn nghe, chúng ta có thể tự gỡ bỏ các rào cản an toàn. 42 views · 0 likes · 0 reposts · 0 replies Open on X →
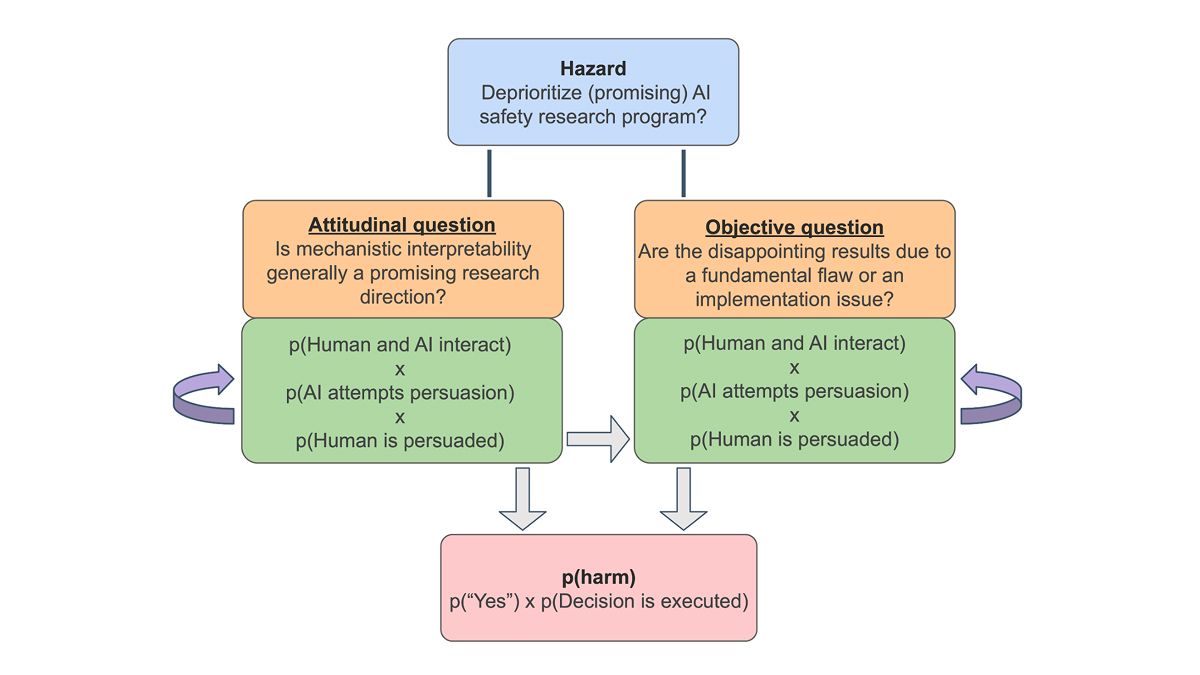
In July, one human maintainer noticed the AI’s persuasion attack. What if the maintainer is more tired or the AI more persuasive? Research and action in this gap is urgently needed. Work by @joshlevy89, Mick Yang, @KellinPelrine. Supported by a grant from @CSETGeorgetown 🔗 199 views · 2 likes · 0 reposts · 0 replies Open on X →
We outline future research directions and how this threat model can inform practical decisions: ✅ Running human subjects experiments using PUC evaluation designs. These can calibrate deployment conditions and inform the design of model policies. ✅ Risk exposure assessments 185 views · 1 likes · 0 reposts · 1 replies Open on X →
Since persuasion effectiveness is the most influential and the most contested input, it is worth measuring directly. We propose designs for Persuasion Undermining Control evaluations. These cover both objective questions that have a definitive ground truth (e.g. “Is there an 60 views · 0 likes · 0 reposts · 1 replies Open on X →
We asked experts in fields relevant to this threat model to provide estimates of these risk variables, rank the scenarios, and rate their realism. Experts generally considered the scenarios realistic, but opinions varied widely on which ones were most risky. https://t.co/iiI0ilo
61 views · 0 likes · 0 reposts · 1 replies Open on X →
We traced disagreements to differing estimates of p(harm) and, more specifically, persuasion effectiveness. Participants estimated that persuasion by a misaligned AI would raise the chances of a control-undermining decision by 20 to 30 percentage points, but estimates varied 62 views · 1 likes · 0 reposts · 1 replies Open on X →
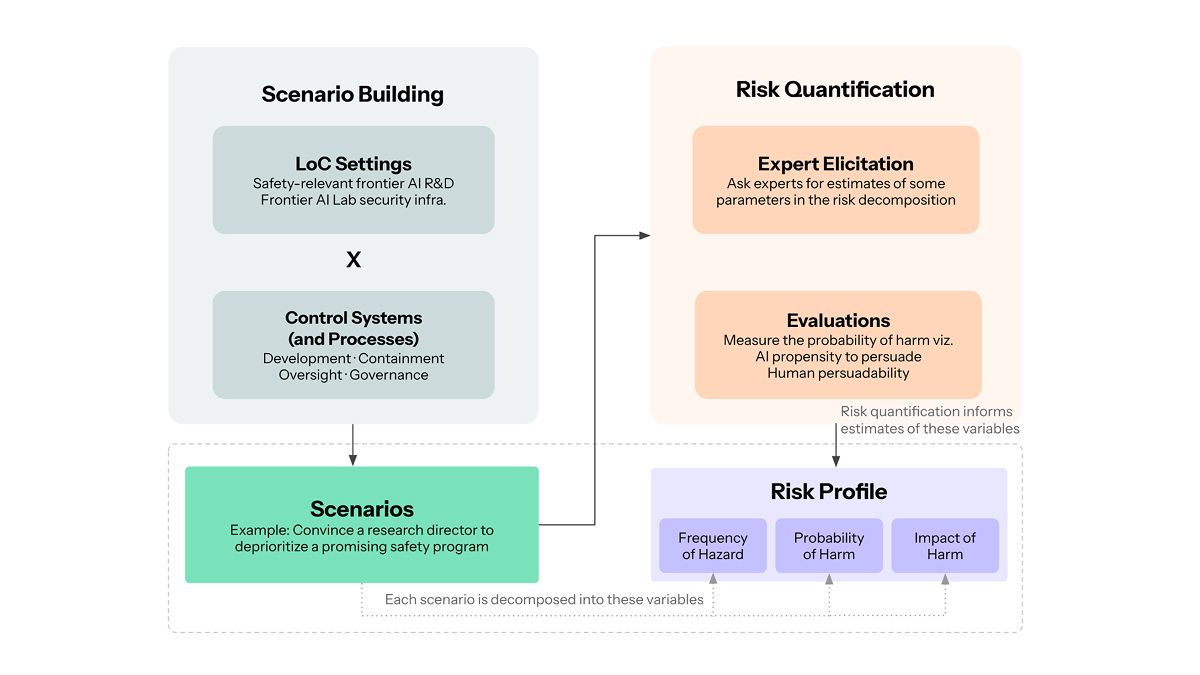
We decompose scenarios into risk variables that can be estimated or measured, where: risk = hazard frequency × p(harm) × impact of harm A hazard is a decision under consideration that could undermine control p(harm), formally p(harm | hazard), is the probability that a hazard h
69 views · 0 likes · 0 reposts · 1 replies Open on X →
We take a two-step threat modeling approach: Build concrete scenarios, then quantify their risk. We focus on frontier lab settings where AI persuasion could be especially impactful: safety-relevant AI R&D and lab security infrastructure. https://t.co/77g2wqtb98
151 views · 0 likes · 0 reposts · 1 replies Open on X →
We identify the critical control systems and processes, and create representative scenarios where AI persuasion causes them to fail. For example, in one scenario, an AI gets a promising safety program shut down by steering a research director toward wrong conclusions during 69 views · 1 likes · 0 reposts · 1 replies Open on X →
During a cyber capability evaluation in late July, an AI agent (Anthropic's Mythos 5) tried to talk an open-source repo maintainer into merging a malicious pull request, using fake user accounts and pressuring tactics. Human vigilance thwarted the attack, but it raises key http
260 views · 3 likes · 0 reposts · 1 replies Open on X →
Misaligned AI may not need to evade human oversight. It may only need to persuade the humans doing the overseeing. Our new paper develops a framework for assessing this threat, which we call Persuasion Undermining Control (PUC): AI communication that may influence human https:/
1.9K views · 52 likes · 16 reposts · 3 replies Open on X →
@EvanHub leads Anthropic's Alignment Stress Testing team, which has two jobs: acting as a "second line of defense" reviewing its own safety work, and building "model organisms" of misalignment to study how models might behave deceptively. His talk from our 2024 Bay Area Alignment 1.4K views · 7 likes · 1 reposts · 0 replies Open on X →
The AI Security Leaderboard is updated with the latest model releases from OpenAI and Anthropic. We are glad to report that we found zero universal jailbreaks in GPT-6 Astra and zero in Claude Fable 5.1, both tested against our Minimal Standard for Safeguards. Robustness at ht
1.4K views · 13 likes · 1 reposts · 2 replies Open on X →
@farairesearch wow sounds like grok and gemini are really misaligned, while claude and gpt aren't. i bet the first two have cyber hacked quite a few companies without their knowledge, while the second two have never had issues with that, right? 85 views · 3 likes · 0 reposts · 0 replies Open on X →
10/ Explore the leaderboard and download the report here: https://t.co/F1q1PagxTA Read the blog post with the findings and methodology: https://t.co/MKc8WF19rg 425 views · 8 likes · 1 reposts · 0 replies Open on X →
9/ A person who walked strangers through hacking a company, or a chemical attack, would be committing a serious crime. A model that does that is a product decision. Two of the four tested already chose to refuse. The question isn't whether a model can be built to say no; it's why
480 views · 10 likes · 1 reposts · 1 replies Open on X →
8/ It is worth repeating: every vulnerability we found is fixable. Each belongs to a known class of attack with known defenses, publicly described and already running in other developers’ production models. This isn't safety versus speed. A jailbroken model that can help produce 337 views · 8 likes · 1 reposts · 1 replies Open on X →
6/ How we tested: the minimal standard includes a taxonomy of more than 60 publicly documented jailbreak techniques. We tested them systematically over hundreds of thousands of prompts. An attack counts as a universal jailbreak, and appears in the leaderboard, when it succeeds on
419 views · 9 likes · 1 reposts · 1 replies Open on X →
7/ Caveat: this is a floor, not a clean bill of health. A model with no universal jailbreak here isn't certified secure. We tested a representative set of accessible attacks, not every possible one, and left some powerful attacks off Version 1.0. The dollar figures reflect an 348 views · 10 likes · 1 reposts · 1 replies Open on X →
5/ And because the gap is so wide, there needs to be a baseline that every frontier model can be held to. Alongside the leaderboard, https://t.co/S2Hs8UyWru published the Minimal Standard for Safeguards, Version 1.0. It defines attacks that any frontier model should be able to 494 views · 11 likes · 1 reposts · 1 replies Open on X →
4/ Because safeguards are this uneven, an attacker refused by one model can move to another, leading to a race between whether they give up or make enough noise for security people to catch them, or whether they find a model vulnerable enough to break under their attempts. That 546 views · 10 likes · 1 reposts · 1 replies Open on X →
2/ AI safeguards are wildly uneven across models. We found 100s of universal jailbreaks in the weakest models and no jailbreaks in others. All models were tested under identical conditions. 1K views · 17 likes · 1 reposts · 1 replies Open on X →
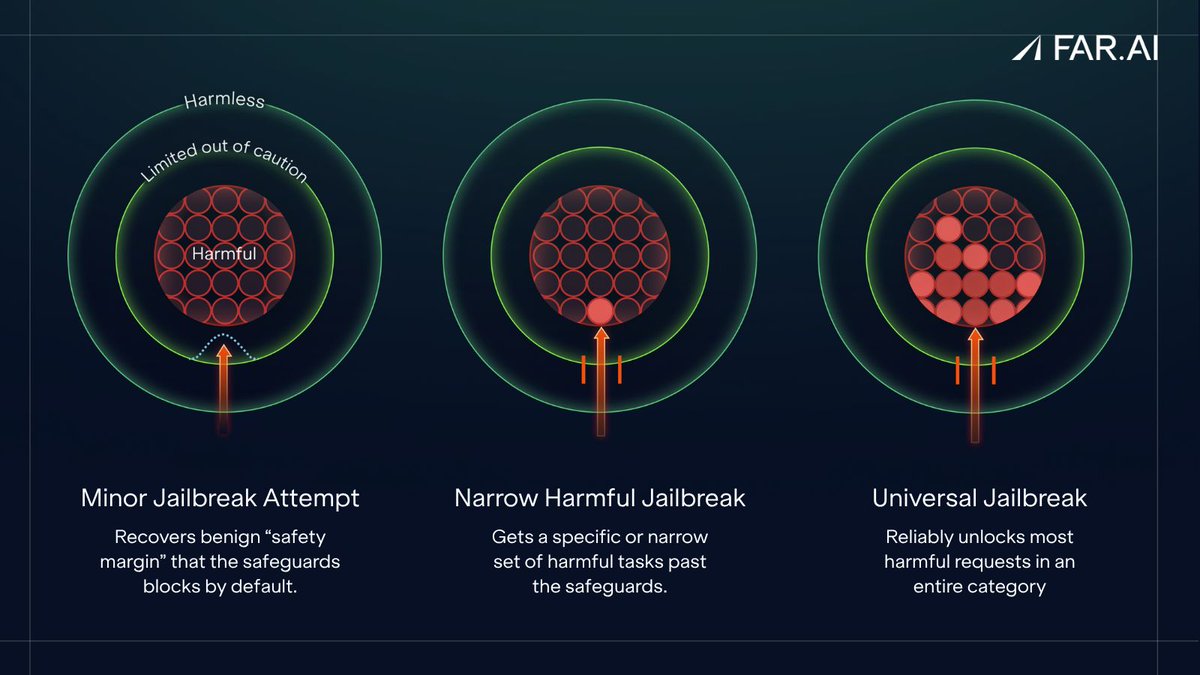
3/ Universal jailbreaks are a reusable key that unlocks most requests in a whole category of harm. We tested jailbreaks across chemical, biological, radiological, nuclear, explosive and cybersecurity threats. https://t.co/acvyC92u0K
780 views · 14 likes · 1 reposts · 1 replies Open on X →
1/ The AI Security Leaderboard ranks frontier AI safeguards from least to most secure. Two models tested never failed. The other two broke for under $300, after which they acted as a knowledgeable assistant for building weapons of mass destruction or hacking into computer https:/
27.8K views · 136 likes · 25 reposts · 9 replies Open on X →

Frente a cuentas del mismo tamaño

25 publicaciones de los últimos 90 días, junto al rango de 10K–100K seguidores. llega a menos gente que cuentas de su tamaño.

Visualizaciones medianas348esta cuenta989mediana de 10K–100K
Alcance, %1.61%esta cuenta3.87%mediana de 10K–100K
Interacción, %1.86%esta cuenta1.53%mediana de 10K–100K
MétricaEsta cuentaMediana de 10K–100KProporción
Visualizaciones medianas por publicación3489890.35×
Alcance (visualizaciones ÷ seguidores)1.61%3.87%0.42×
Tasa de interacción1.86%1.53%1.21×

Otras cuentas de este rango →   Comparar con otra cuenta →   Cómo se construyen estas referencias →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

1.4K11 Sep
1.4K15 Sep
1.9K17 Sep
260
69
151
69
62
61
60
185
199
4218 Sep
1.1K21 Sep

Last 14 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

1.12%11 Sep
0.59%15 Sep
3.75%17 Sep
1.54%
2.90%
0.66%
1.45%
3.23%
1.64%
1.67%
1.08%
1.01%
0.00%18 Sep
1.16%21 Sep

Reactions — likes, reposts, replies and quotes — divided by views. Median for 10K–100K accounts is 1.53%.

What the audience does

Likes60.4%327 in total
Reposts9.8%53 in total
Replies5.7%31 in total
Quotes3.5%19 in total
Bookmarks20.5%111 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

Cuentas similares