tweetindex
EN

Artificial Analysis ✓

@ArtificialAnlys · San Francisco · joined 06 Jan 2024

Independent analysis of AI

149 347Followers
679Following
3 349Posts total
16.2MViews on collected posts

Latest posts

@ArtificialAnlys @Xiaomi ☠️ https://t.co/2OsrO9WWCw
8.6K views · 184 likes · 10 reposts · 6 replies Open on X →
@ArtificialAnlys @Xiaomi Better than Grok 4.7 😆 11.5K views · 251 likes · 1 reposts · 5 replies Open on X →
@ArtificialAnlys @Xiaomi numbers are looking very attractive 4.2K views · 83 likes · 0 reposts · 0 replies Open on X →
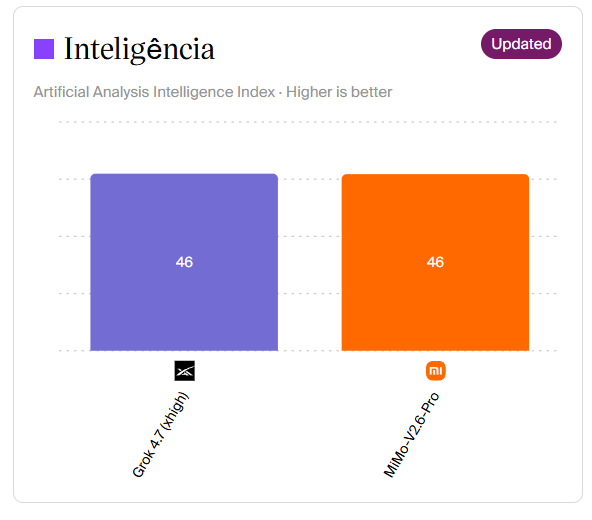
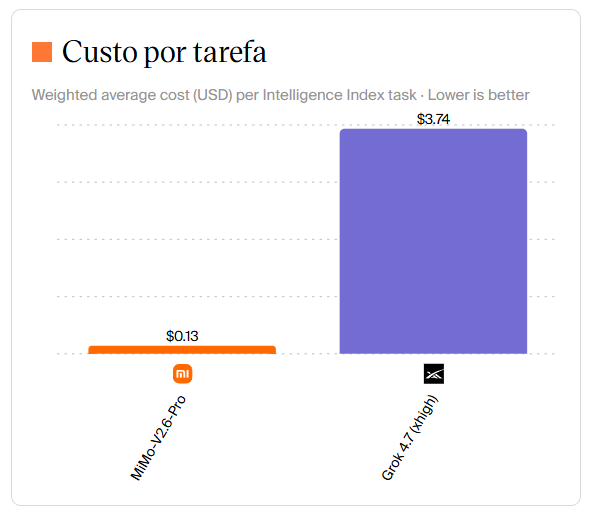
MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier @Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major h
827.8K views · 4K likes · 380 reposts · 157 replies Open on X →
@ArtificialAnlys You should add benchmarks for spatial reasoning, CAD, kernels, electrical engineering and robot control at the very least. Your new aggregate is super outdated and incapable of capturing emerging relevant capabilities. 2.6K views · 91 likes · 0 reposts · 2 replies Open on X →
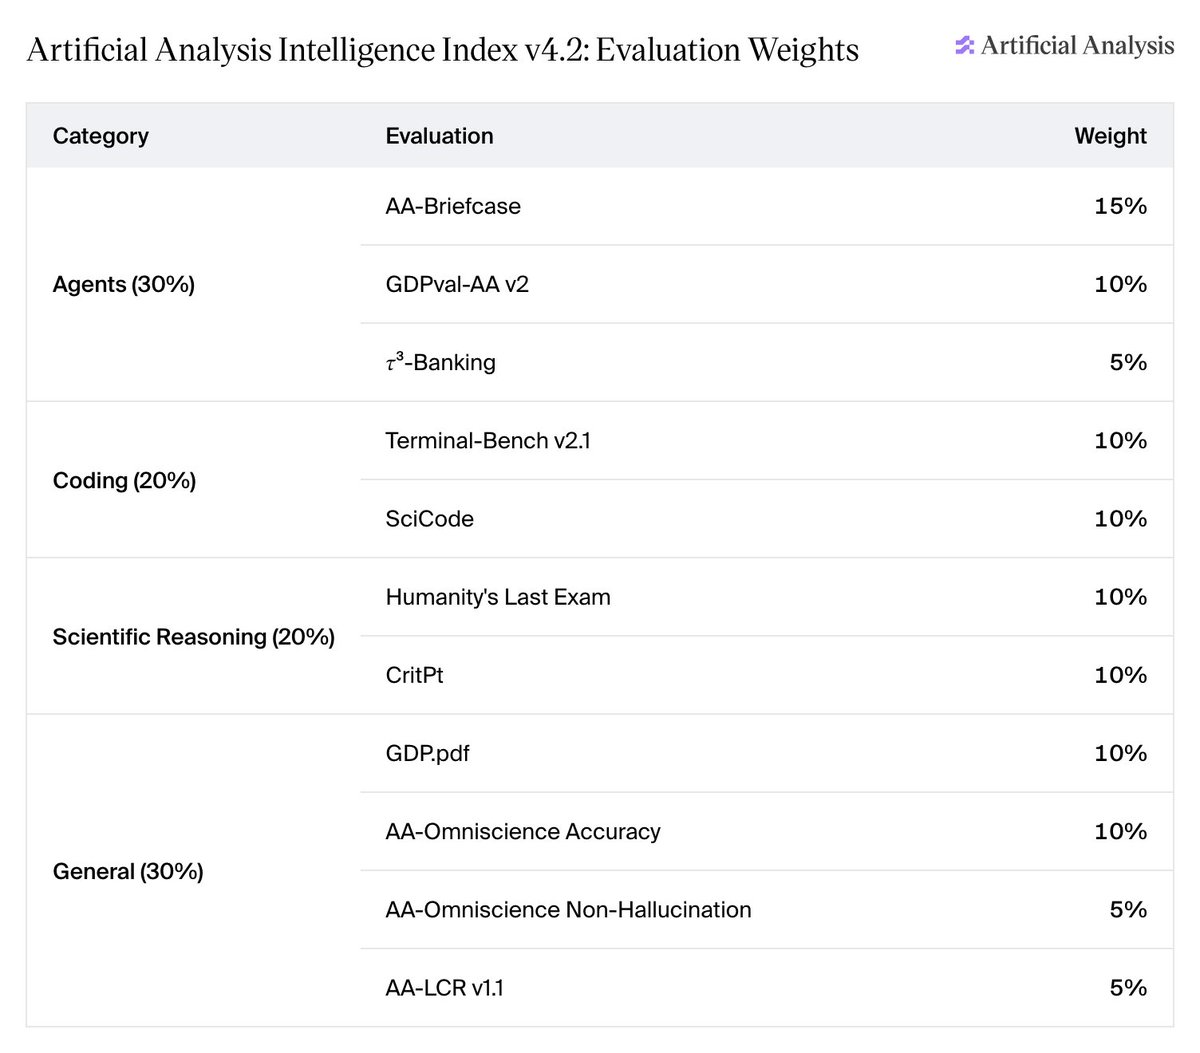
As always, our full methodology is available: https://t.co/lxq6rcXfNK Category contributions to the Intelligence Index remain at Agents: 30%, Coding: 20%, General: 30%, and Scientific Reasoning: 20%. Terminal-Bench 4.0 keeps the same weighting as Terminal-Bench 2.1, and https://
7.8K views · 47 likes · 2 reposts · 1 replies Open on X →
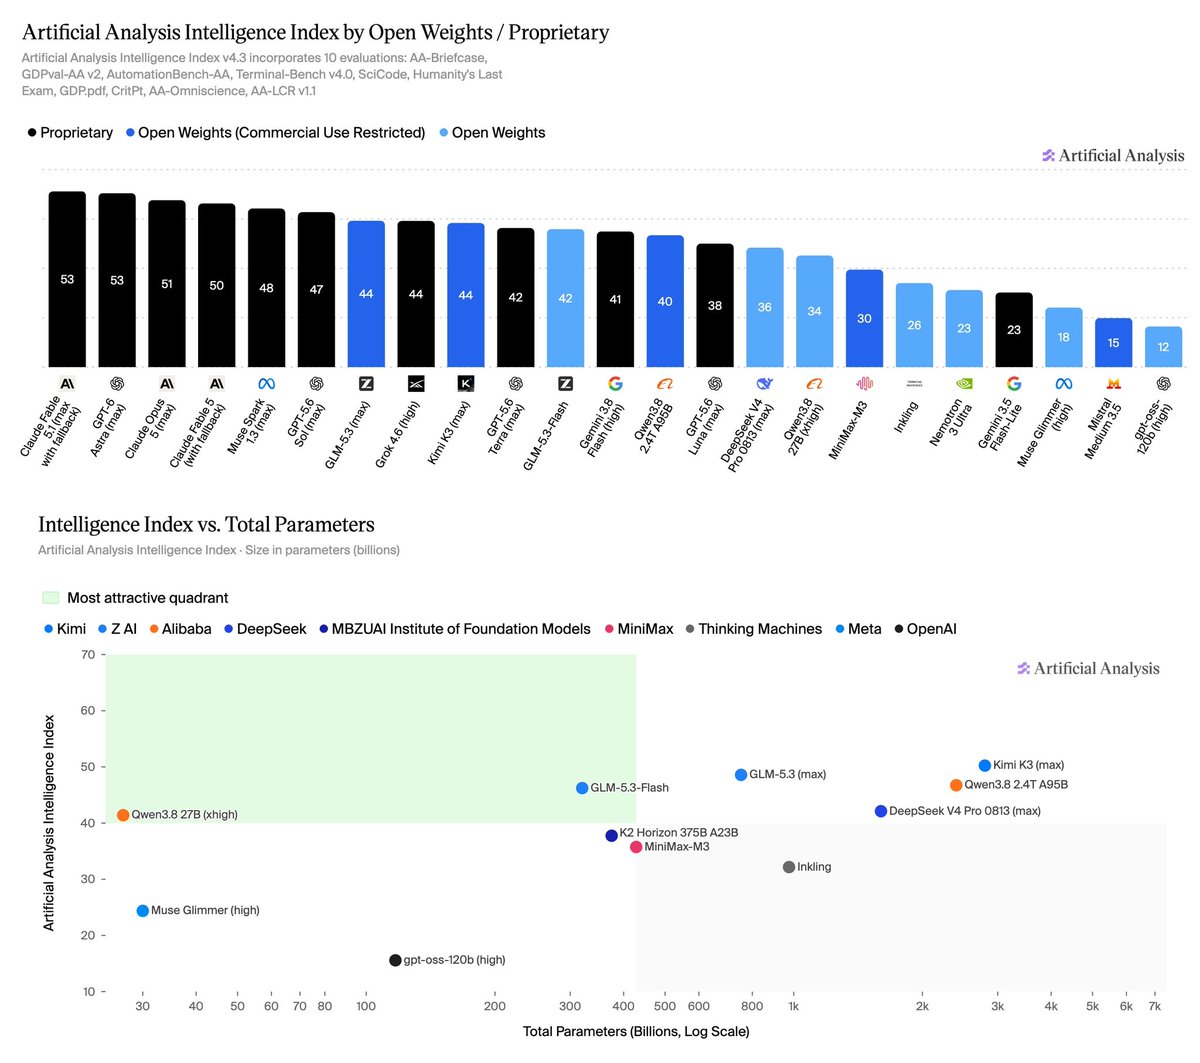
GLM-5.3 and Kimi K3 continue to lead open weights models at 44, followed by GLM-5.3-Flash (42), Qwen3.8 2.4T A95B (40) and DeepSeek V4 Pro 0813 (max, 36). That puts both leading open weights models 9 points behind Claude Fable 5.1 and GPT-6 Astra, which both score 53 https://t.co
6.2K views · 42 likes · 2 reposts · 2 replies Open on X →
Similar Intelligence Index scores can come at very different costs. GPT-6 Astra (max) and Claude Fable 5.1 (max with fallback) both score 53, but their average Cost per Intelligence Index Task is $3.26 and $7.63 respectively - 57% lower for GPT-6 Astra GLM-5.3-Flash and GPT-5.6
8.5K views · 51 likes · 2 reposts · 1 replies Open on X →
We are upgrading from Terminal-Bench 2.1 to 4.0, which features harder tasks from a terminal. Terminal-Bench 4.0 tests whether an agent can complete complex work through the terminal, across software, machine learning, science, operations, security, hardware, and media. The https
11K views · 107 likes · 4 reposts · 4 replies Open on X →
We are replacing 𝜏³-Banking with AutomationBench-AA, featuring broader business workflows across applications In collaboration with Zapier, we run the held-out test set of 657 tasks, using the v1.0.6 version of the benchmark. We call our implementation AutomationBench-AA https:/
8.1K views · 65 likes · 3 reposts · 1 replies Open on X →
@ArtificialAnlys Modified it after the astra backlash 🤣🤣 11.6K views · 480 likes · 0 reposts · 5 replies Open on X →
Disclosure of full methodology at https://t.co/z8DCRfynZL https://t.co/jAxlKI0GH3
19.6K views · 74 likes · 2 reposts · 1 replies Open on X →
Full per-model breakdowns below: https://t.co/M5x0BOEL5e
21.9K views · 81 likes · 2 reposts · 2 replies Open on X →
OpenAI leads GDP.pdf with GPT-6 Astra at 33.2% and GPT-5.6 Sol at 28.2%, followed by Claude Fable 5.1 at 26.2%. Created by @HelloSurgeAI, GDP.pdf evaluates single-turn professional document reasoning across 100 PDFs and ten domains. Models must synthesize evidence distributed ht
21.5K views · 81 likes · 1 reposts · 3 replies Open on X →
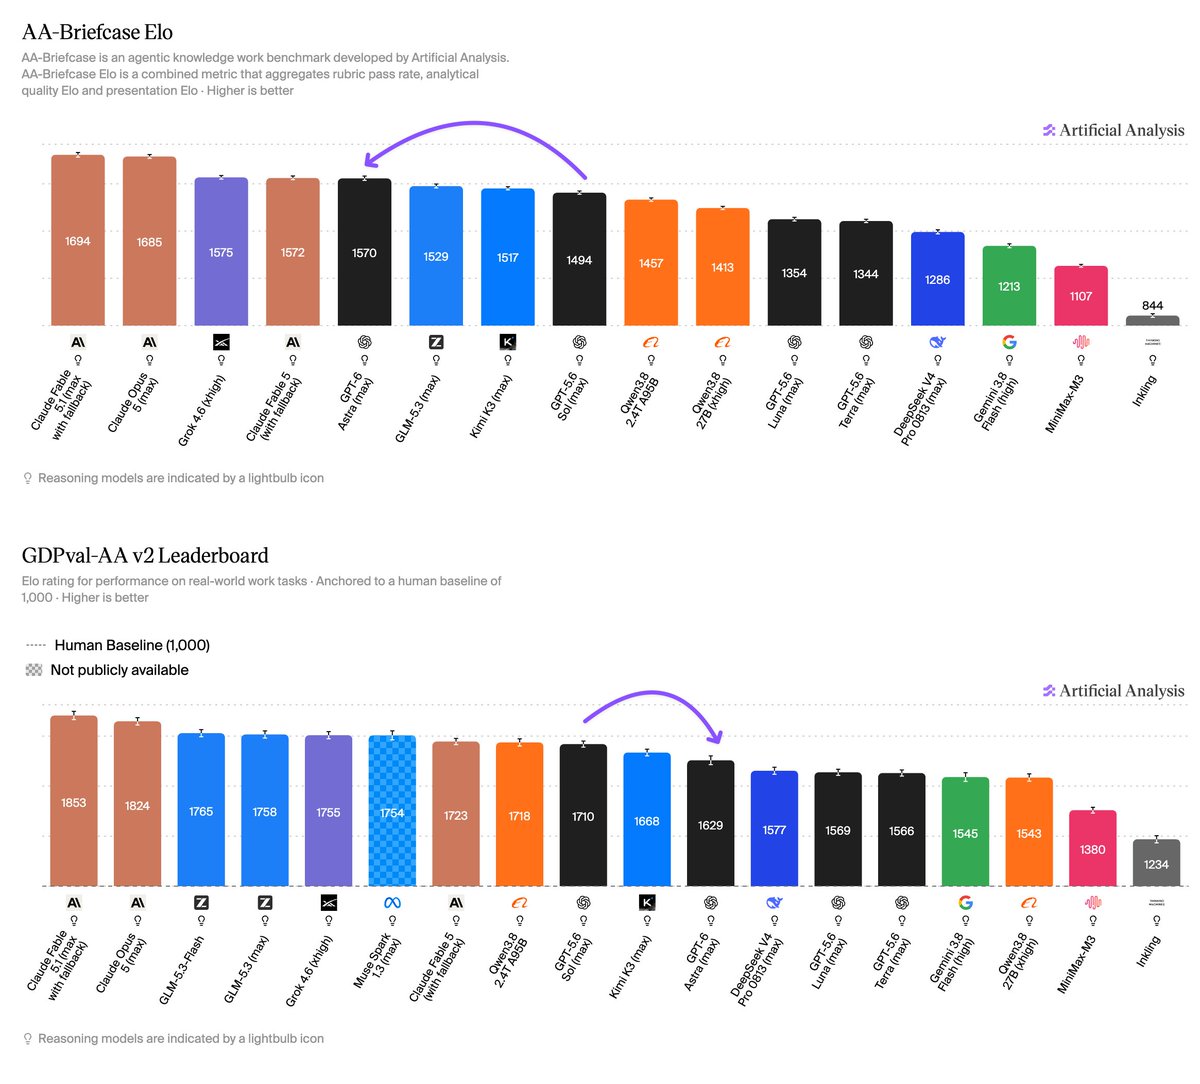
Anthropic’s Claude Fable 5.1 and Opus 5 lead AA-Briefcase, followed by GPT-6 Astra and Muse Spark 1.3. GPT-6 Astra shows a substantial gain above GPT-5.6 Sol of ~85 Elo points. AA-Briefcase is our frontier in-house evaluation with a private held-out test set. The evaluation http
27.9K views · 113 likes · 3 reposts · 4 replies Open on X →
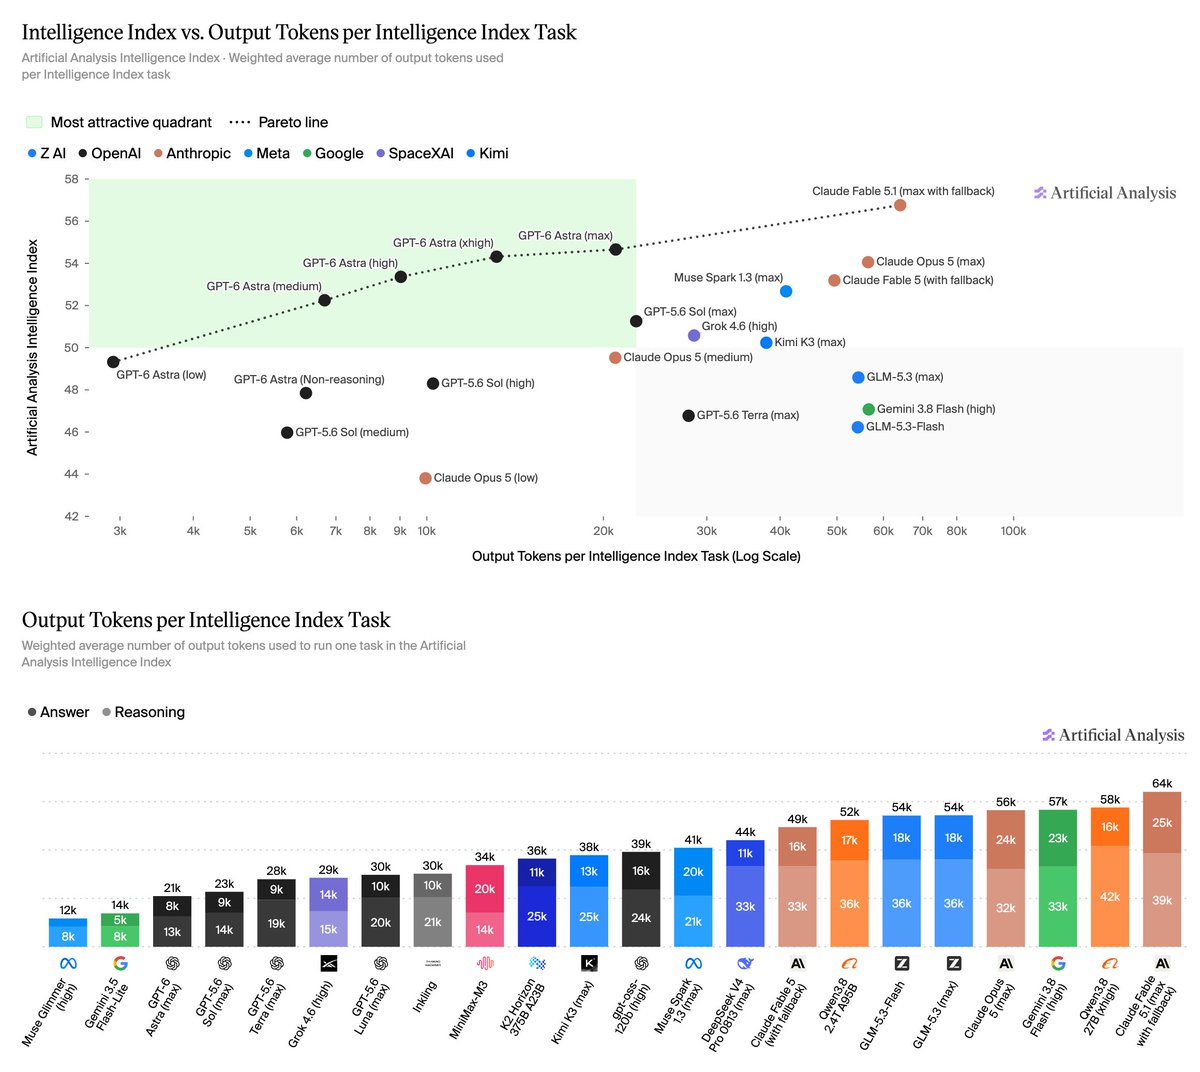
GPT-6 Astra is more token efficient than almost every other model near the intelligence frontier, with Claude Fable 5.1 and Gemini 3.8 Flash using the most tokens of models scoring at least 25 on our Index. https://t.co/p3gpxrA1ZT
43.2K views · 318 likes · 18 reposts · 9 replies Open on X →
Announcing Artificial Analysis Intelligence Index v4.2. We are accelerating elements of our upcoming v5 release with interim updates to keep pace with the frontier. Index v4.2 has more complex and realistic tasks, and more private test sets to prevent gaming Intelligence Index h
1.4M views · 2.5K likes · 202 reposts · 237 replies Open on X →
@ArtificialAnlys @grok I'm only interested in intelligence and reasoning benchmark. Cut the fluff, be brutally politically incorrect and provide the objective truth. Thanks bro! 178 views · 1 likes · 0 reposts · 1 replies Open on X →
@ArtificialAnlys 🚀 https://t.co/y6Opm7Ls6Q
24.7K views · 579 likes · 9 reposts · 10 replies Open on X →
Compare GPT-6 Astra with other leading models at: https://t.co/skF71jqPrM 33.6K views · 70 likes · 2 reposts · 5 replies Open on X →
Breakdown of the individual evaluations in the Artificial Analysis Intelligence Index v4.1.1. https://t.co/iXNkA7GPtW
45.4K views · 96 likes · 3 reposts · 1 replies Open on X →
The model shows mixed progress in agentic knowledge work - improving ~80 points in AA-Briefcase, but regressing a similar amount in GDPval-AA v2. In AA-Briefcase, Astra sees a significant increase in both rubric scores and Analytical Quality Elo, but a reduction in Presentation h
36.9K views · 84 likes · 2 reposts · 1 replies Open on X →
GPT-6 Astra sees a large jump in AA-Omniscience, driven by a significant decrease in hallucination rate from 92% to 51% at max effort, alongside a modest increase in accuracy. https://t.co/DPlbtNuwpP
45.1K views · 130 likes · 6 reposts · 4 replies Open on X →
GPT-6 Astra is 75% more expensive than GPT-5.6 Sol at max effort, and largely sits behind its predecessor on the Intelligence Index vs Cost per Task frontier. This is driven by a 2.5x increase in price, partially offset by a reduction in token use. https://t.co/0dm58IpWNF
47.4K views · 141 likes · 6 reposts · 6 replies Open on X →
GPT-6 Astra defines a new Pareto frontier for Intelligence Index vs Output Tokens per Task - with a ~10% reduction in output tokens at max effort compared to GPT-5.6 Sol. https://t.co/3whEm4EHL0
314.8K views · 326 likes · 24 reposts · 9 replies Open on X →
GPT-6 Astra is on the Pareto frontier for Coding Agent Index vs Cost per Task, with its max effort setting costing about the same as GPT-5.6 Sol (max) while scoring 2 points higher in the Index. https://t.co/F6tYa23czh
58.7K views · 194 likes · 12 reposts · 5 replies Open on X →
Coding Agent Index cost improvements are driven by token efficiency, with a ~3x token reduction at max effort compared to GPT-5.6 Sol (max). https://t.co/AGbQ1lXGVk
68.8K views · 226 likes · 14 reposts · 5 replies Open on X →
GPT-6 Astra makes significant gains in the Artificial Analysis Coding Agent Index, scoring equal to Fable 5 at lower cost. In the Intelligence Index, it uses fewer tokens than GPT-5.6 Sol for similar performance, but this is outweighed by higher prices Pricing is 2.5x GPT-5.6 ht
1.7M views · 2.9K likes · 339 reposts · 392 replies Open on X →
@ArtificialAnlys Ok, even the fucking UAE !? EUROPE !! WAKE UUUUPP ! RELEASE COMPRESSED KIMI K3 NOW ! 397 views · 3 likes · 0 reposts · 0 replies Open on X →
See Artificial Analysis for further details and benchmarks of K2 Horizon 375B A23B: https://t.co/tgrlKYoUYZ 3.9K views · 6 likes · 0 reposts · 1 replies Open on X →

Against accounts of the same size

74 posts from the last 90 days, next to the 100K–1M follower range. shown widely, but few of those viewers react.

Median views10 880this account5 983median for 100K–1M
Reach, %7.29%this account1.49%median for 100K–1M
Engagement, %0.59%this account0.93%median for 100K–1M
MetricThis accountMedian for 100K–1MRatio
Median views per post10 8805 9831.82×
Reach (views ÷ followers)7.29%1.49%4.89×
Engagement rate0.59%0.93%0.63×

Others in this range →   Compare with another account →   How these benchmarks are built →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

21.5K4 Sep
21.9K
19.6K
11.6K
8.1K7 Sep
11K
8.5K
6.2K
7.8K
2.6K
827.8K21 Sep
4.2K
11.5K
8.6K

Last 14 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

0.40%4 Sep
0.39%
0.39%
4.18%
0.86%7 Sep
1.05%
0.66%
0.76%
0.64%
3.59%
0.58%21 Sep
1.97%
2.23%
2.36%

Reactions — likes, reposts, replies and quotes — divided by views. Median for 100K–1M accounts is 0.93%.

What the audience does

Likes72.7%13 450 in total
Reposts5.7%1 049 in total
Replies4.8%880 in total
Quotes4.6%846 in total
Bookmarks12.3%2 266 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

Similar accounts