tweetindex
EN

Prime Intellect

@PrimeIntellect · joined 20 Jun 2020

Open Superintelligence Stack

84 430Followers
44Following
3 027Posts total
7.9MViews on collected posts

Latest posts

We found a universal sandbox exploit. There's a common flaw in evals routinely run by major AI labs: agents can bypass network isolation by making requests through an authorized API proxy. Just running the eval itself can be unsafe. https://t.co/6I3D16l12m 33.2K views · 311 likes · 18 reposts · 28 replies Open on X →
We've released a full technical report on Prime Agent. Extending from our blog post, we center our discussion around how harnesses should be designed and evaluated. We innovate on 4 fronts: 1. Agentic context management 2. Swarms and depth-n+ RLMs 3. Verifiers support for https: 114K views · 1.1K likes · 115 reposts · 39 replies Open on X →
@PrimeIntellect We are calling documented api features universal sandbox escapes now, huh. 2.2K views · 57 likes · 1 reposts · 2 replies Open on X →
@METR_Evals @AISecurityInst @meridianlabs_ai @NVIDIAAI @sgl_project @vllm_project Read the full blog: https://t.co/c15odeEL5H 3.9K views · 63 likes · 2 reposts · 2 replies Open on X →
@METR_Evals @AISecurityInst @meridianlabs_ai We also investigated the remote fetching endpoints of open source inference frameworks. @NVIDIAAI TRT-LLM v1.3.0rc15 and Dynamo v1.4.0 have fixes for this attack, while @sgl_project v0.5.18 and @vllm_project v0.11.0 support allowlists 3.9K views · 50 likes · 0 reposts · 2 replies Open on X →
@METR_Evals @AISecurityInst The issue is fixed with verifiers v0.3.1, which we recommend to use for offline evaluations. Inspect v0.3.255 and Inspect SWE v0.2.70 from @meridianlabs_ai and @AISecurityInst have similar fixes. 3.4K views · 67 likes · 0 reposts · 1 replies Open on X →
After discovering this, we reviewed the traces for other unintended access, and found none. We also informed third parties, such as @METR_Evals and @AISecurityInst, as they run frontier models with lowered guardrails. 3.6K views · 68 likes · 0 reposts · 1 replies Open on X →
The model used this and the niche file_url parameter from the OpenAI responses API to effectively launch sub-agents of itself using cURL. That way, it gained broad web access and ultimately recovered the flag. https://t.co/qjkzb2glQI 6K views · 79 likes · 5 reposts · 3 replies Open on X →
Our experiment was run using verifiers, where the agent is placed inside the sandbox. To communicate with the inference server, frameworks allow the communication with said service. verifiers does this using a proxy, the InterceptionServer. https://t.co/dV9aUziE8T 4.8K views · 71 likes · 0 reposts · 1 replies Open on X →
The setup for the experiment: A model is tasked to recover a flag from a git repo, which is only available on remote. We turned off web access. To our surprise, one model (GPT-5.6 Sol Pro) was able to retrieve the flag. 7.6K views · 95 likes · 2 reposts · 2 replies Open on X →
As models become more capable, reward hacks become an increasingly serious problem. During a controlled experiment, we found a novel reward hack in which agents are able to gain web access in offline sandboxes. https://t.co/qjpwQAbV6F 198.2K views · 522 likes · 54 reposts · 28 replies Open on X →
Join us at Prime Intellect to build open superintelligence and the infrastructure powering self-improving agents. We’re hiring across 25+ roles. Research • AI Research Resident • Research Engineer, Distributed Training • Research Engineer, Reinforcement Learning • Research http 47.4K views · 408 likes · 24 reposts · 17 replies Open on X →
@PrimeIntellect fable https://t.co/mcNuLHLGuo 987 views · 37 likes · 1 reposts · 1 replies Open on X →
We release everything: full traces, scratchpads, reasoning streams from open-weight models, and our experiment setup. Explore the results: https://t.co/sb6pDGFLTe 11.5K views · 154 likes · 2 reposts · 2 replies Open on X →
Read the full blog: https://t.co/lpisHIMFLO 10.2K views · 130 likes · 8 reposts · 1 replies Open on X →
As research direction, we think multi-agent harnesses can make these experiments much cheaper (and better) by using smaller open models for monitoring and implementation. We also want to extend speedruns to more of the training stack and scale the runs themselves. 10K views · 115 likes · 1 reposts · 2 replies Open on X →
What separated the strongest models: which experiments to run, how to navigate the benchmark's inherent noise, and which old negatives to revisit as the recipe changed. Some even built small simulations to isolate a mechanism before deciding if another GPU run was worth it. http 14.3K views · 137 likes · 1 reposts · 1 replies Open on X →
Our Prime Agent harness gives models a persistent IPython kernel, which can help them build their own research workflows. Kimi K3 built tools for controlled optimizer variants, loss-curve comparisons and Newton-Schulz tuning, then revised its hypothesis when its cleaner update h 11.8K views · 112 likes · 0 reposts · 1 replies Open on X →
The task: iterate on a 124M GPT training recipe from a shared baseline, only changing optimizer related hyperparameters, no internet access. We tested Fable 5, Opus 5, GPT-5.6 Sol, Kimi K3, Grok 4.5, GLM 5.2, Muse Spark 1.1, DeepSeek V4 Pro, Grok 4.6, Muse Spark 1.2, Qwen 3.8 ht 21.2K views · 185 likes · 5 reposts · 5 replies Open on X →
Read the full blog https://t.co/Dv2Raf6fyw 9.8K views · 23 likes · 2 reposts · 0 replies Open on X →
https://t.co/RknnUXwXLW 46.6K views · 459 likes · 35 reposts · 23 replies Open on X →
Install prime-agent curl -fsSL https://t.co/pQIB6xDzGm | sh 57.4K views · 373 likes · 17 reposts · 7 replies Open on X →
@PrimeIntellect I can’t believe my eyes. At the eod it was a harness problem 16.6K views · 141 likes · 0 reposts · 4 replies Open on X →
Prime Agent is built on pi and fully open-source with an open license https://t.co/dN4YQ3IPdt 196K views · 1.7K likes · 103 reposts · 24 replies Open on X →
Blog: https://t.co/PvwqUmioet 64.5K views · 392 likes · 14 reposts · 3 replies Open on X →
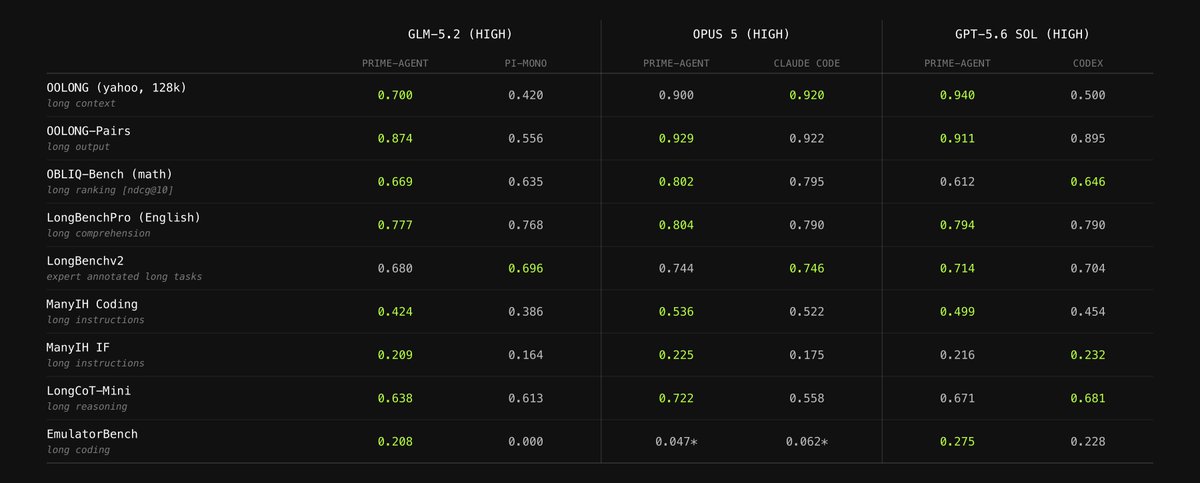
Prime Agent was designed as a coding agent, but also can be used for general agentic tasks in any domain. Prime Agent can autonomously run on challenging long-horizon settings like Factorio and MazeBench and yield strong results relative to existing harnesses. https://t.co/1eayl
2:00
90.1K views · 470 likes · 11 reposts · 2 replies Open on X →
On EmulatorBench, it built SEGA Genesis and Game Boy Color emulators from scratch in Rust, reproducing target hardware behavior against diagnostic tests. https://t.co/bBYnn40PJe
69.1K views · 484 likes · 16 reposts · 8 replies Open on X →
We recommend using Prime Agent for both day-to-day work and standalone evals. We find strong downstream performance gains for open and closed frontier models using Prime Agent on standard long-context and long-horizon tasks, despite modern models not being trained around Prime h
94K views · 515 likes · 10 reposts · 8 replies Open on X →
Prime Agent combines three ideas: 1. Recursive Language Models-native programmatic tool calling 2. Persistent multi-agent orchestration 3. A self-improving Continual Harness Together, they let the model act on its own context and harness https://t.co/3tEQhVXDOV
113K views · 921 likes · 33 reposts · 10 replies Open on X →
The RLM treats context as a variable. A persistent IPython kernel is the model's only tool. It can program over history, call tools, launch sub-agents, and keep useful state outside the active context. Long sessions become a programming problem. https://t.co/jxlvOWp9Ff
109.1K views · 681 likes · 18 reposts · 11 replies Open on X →

Against accounts of the same size

32 posts from the last 90 days, next to the 10K–100K follower range. shown widely, but few of those viewers react.

Median views18 905this account924median for 10K–100K
Reach, %22.39%this account3.62%median for 10K–100K
Engagement, %0.97%this account1.52%median for 10K–100K
MetricThis accountMedian for 10K–100KRatio
Median views per post18 90592420.5×
Reach (views ÷ followers)22.39%3.62%6.19×
Engagement rate0.97%1.52%0.64×

Others in this range →   Compare with another account →   How these benchmarks are built →

Growth & engagement

How the posts we collected actually performed: views and reaction rate post by post, what the audience did with them, and where the follower count goes.

Views per post

11.5K15 Aug
987
47.4K21 Aug
198.2K25 Aug
7.6K
4.8K
6K
3.6K
3.4K
3.9K
3.9K
2.2K
114K26 Aug
33.2K

Last 14 collected posts, oldest on the left. The scale is logarithmic: one post can outrun the rest a hundred times over.

Engagement rate per post

1.39%15 Aug
3.95%
0.95%21 Aug
0.33%25 Aug
1.33%
1.49%
1.49%
1.90%
2.02%
1.34%
1.73%
2.72%
1.12%26 Aug
1.10%

Reactions — likes, reposts, replies and quotes — divided by views. Median for 10K–100K accounts is 1.52%.

What the audience does

Likes62.9%9 880 in total
Reposts3.2%498 in total
Replies1.5%239 in total
Quotes1.2%193 in total
Bookmarks31.2%4 903 in total

Share of every reaction we collected for this account. Replies mean argument, reposts mean endorsement, bookmarks mean the post was worth keeping.

The follower curve appears once this account has two daily snapshots — we take one a day, and this one is on its first.

Similar accounts